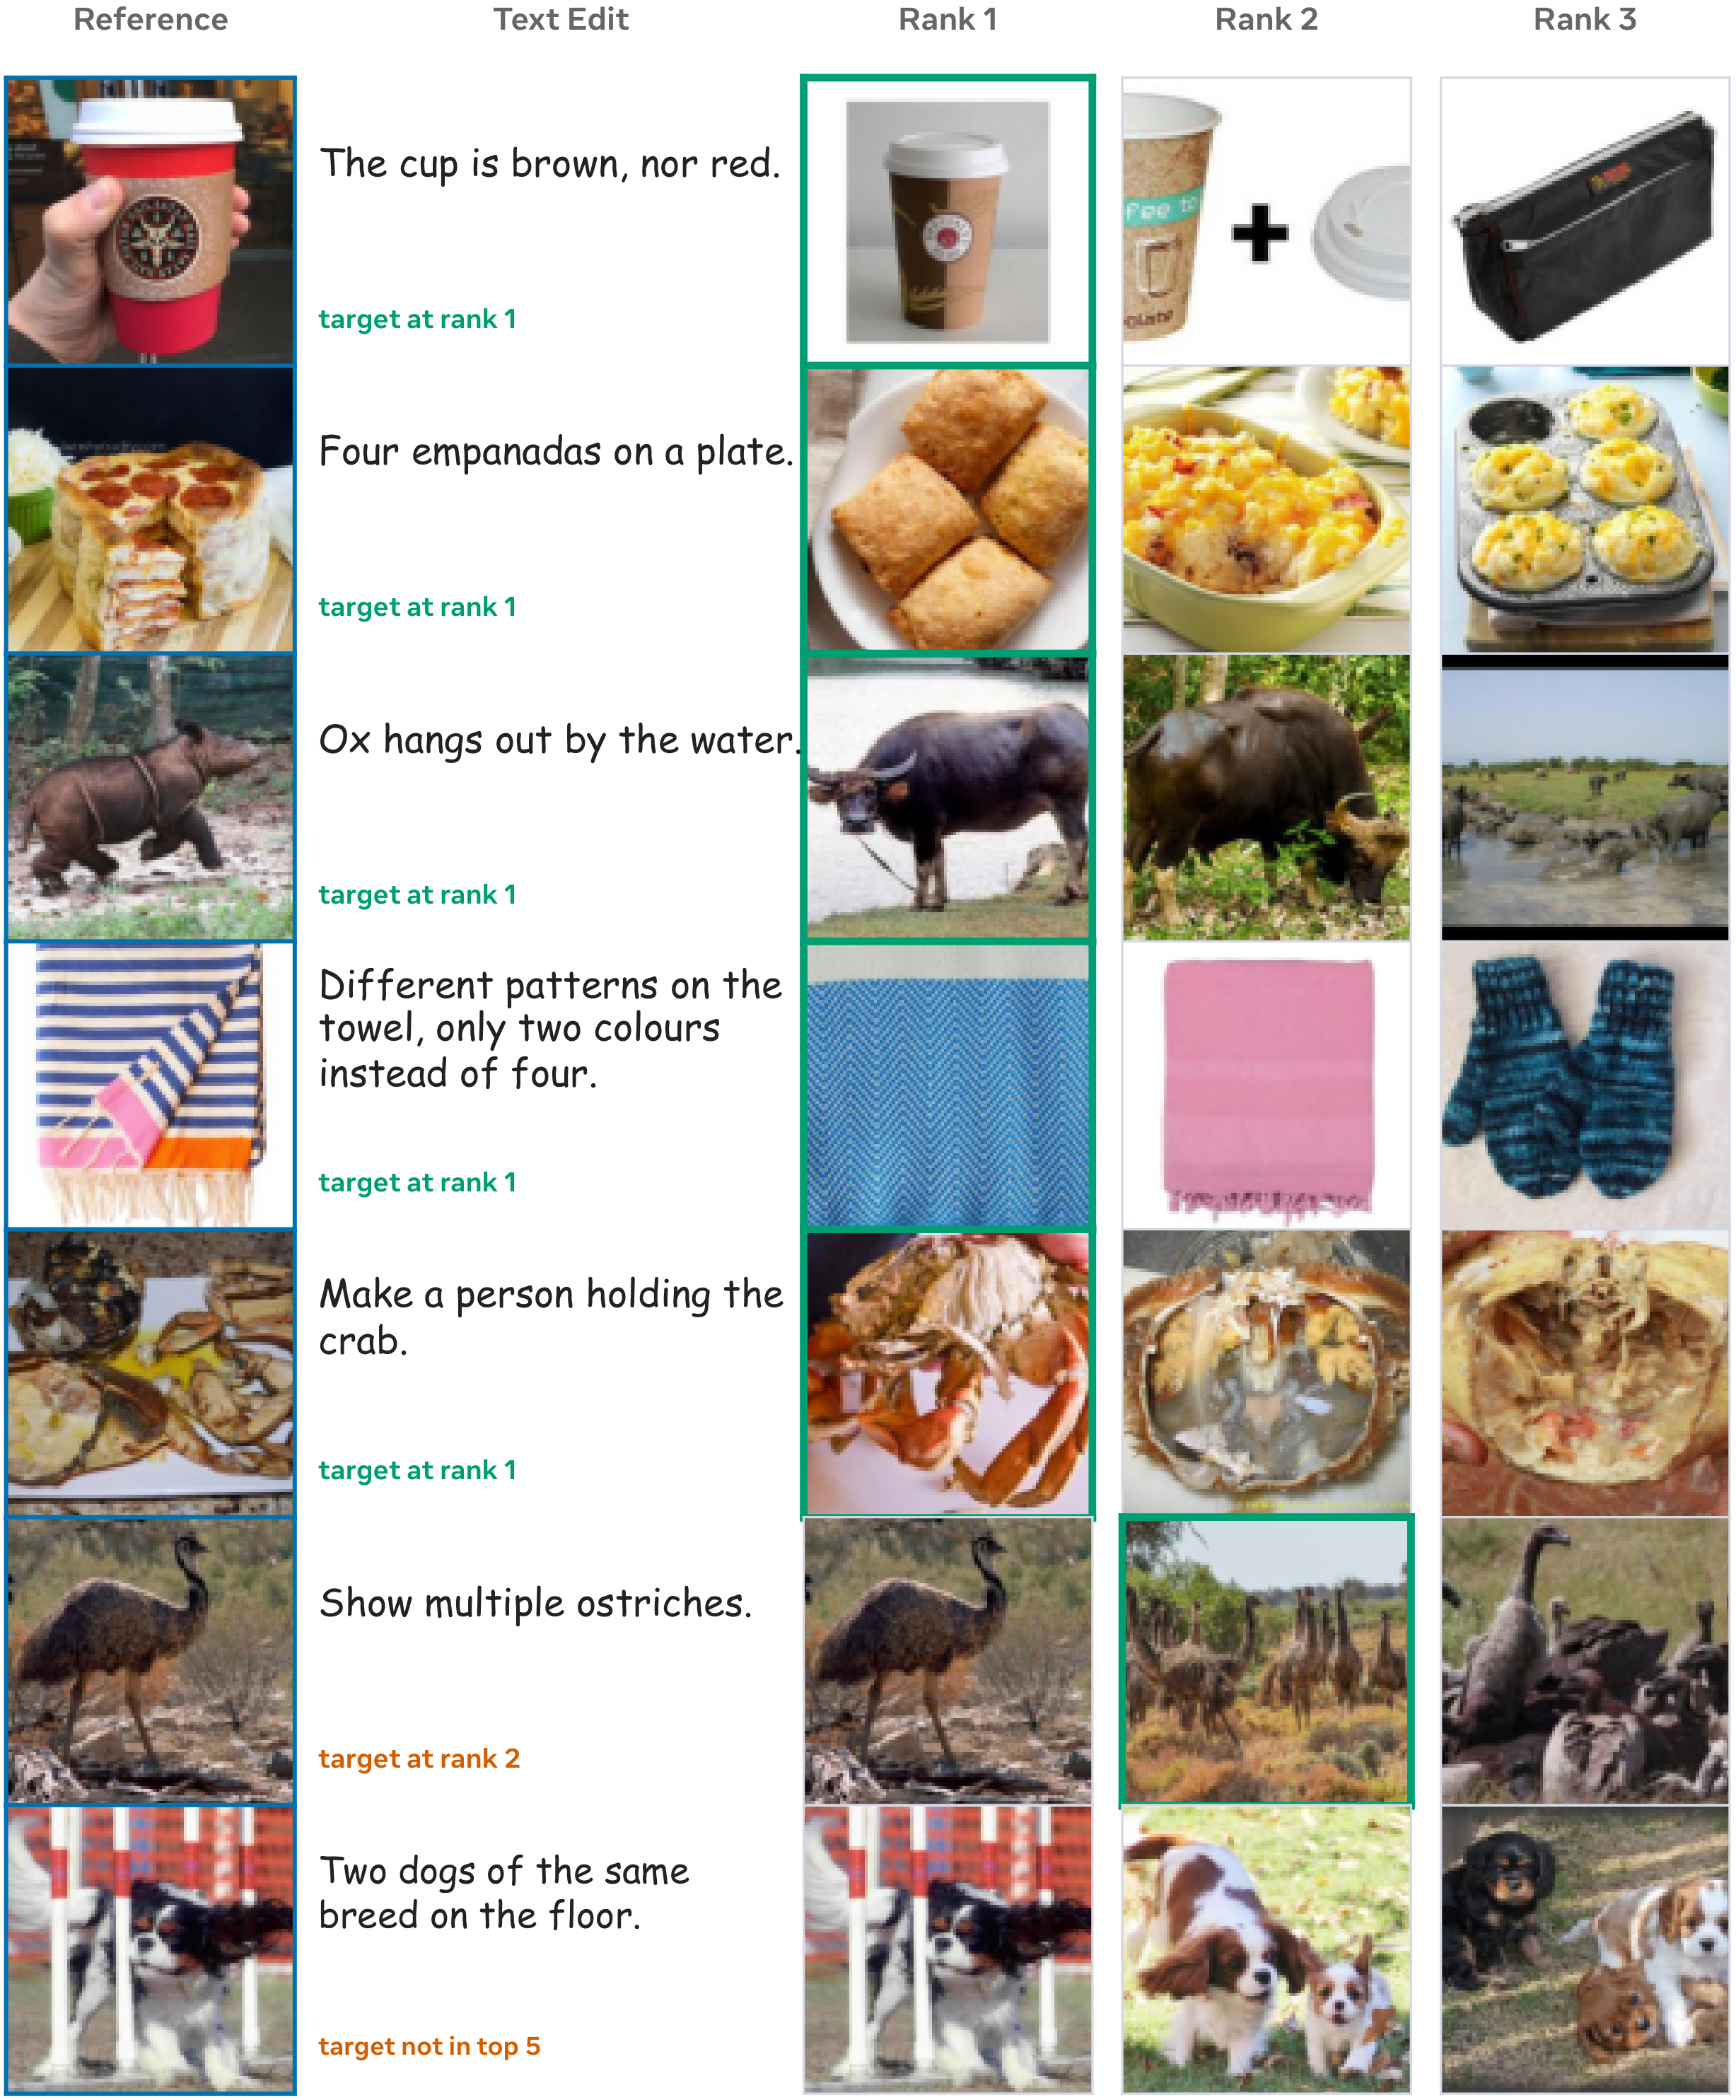
Soft Hard

FLAT

Resampling Image and Text into 1D Flexible-Length Aligned Transmodal Tokens for Retrieval and Generation

Guangyu Sun, Shlok Kumar Mishra, Wentao Bao, Robert Zhenheng Yang, Xiao Wang, Xiyuan Wang, Junrong Mayu, Chen Yuan, Max Xiangjun Fan, Jun Xiao, Jianpeng Cheng

Meta AI

FLAT represents image and text with one shared flexible-length sequence.
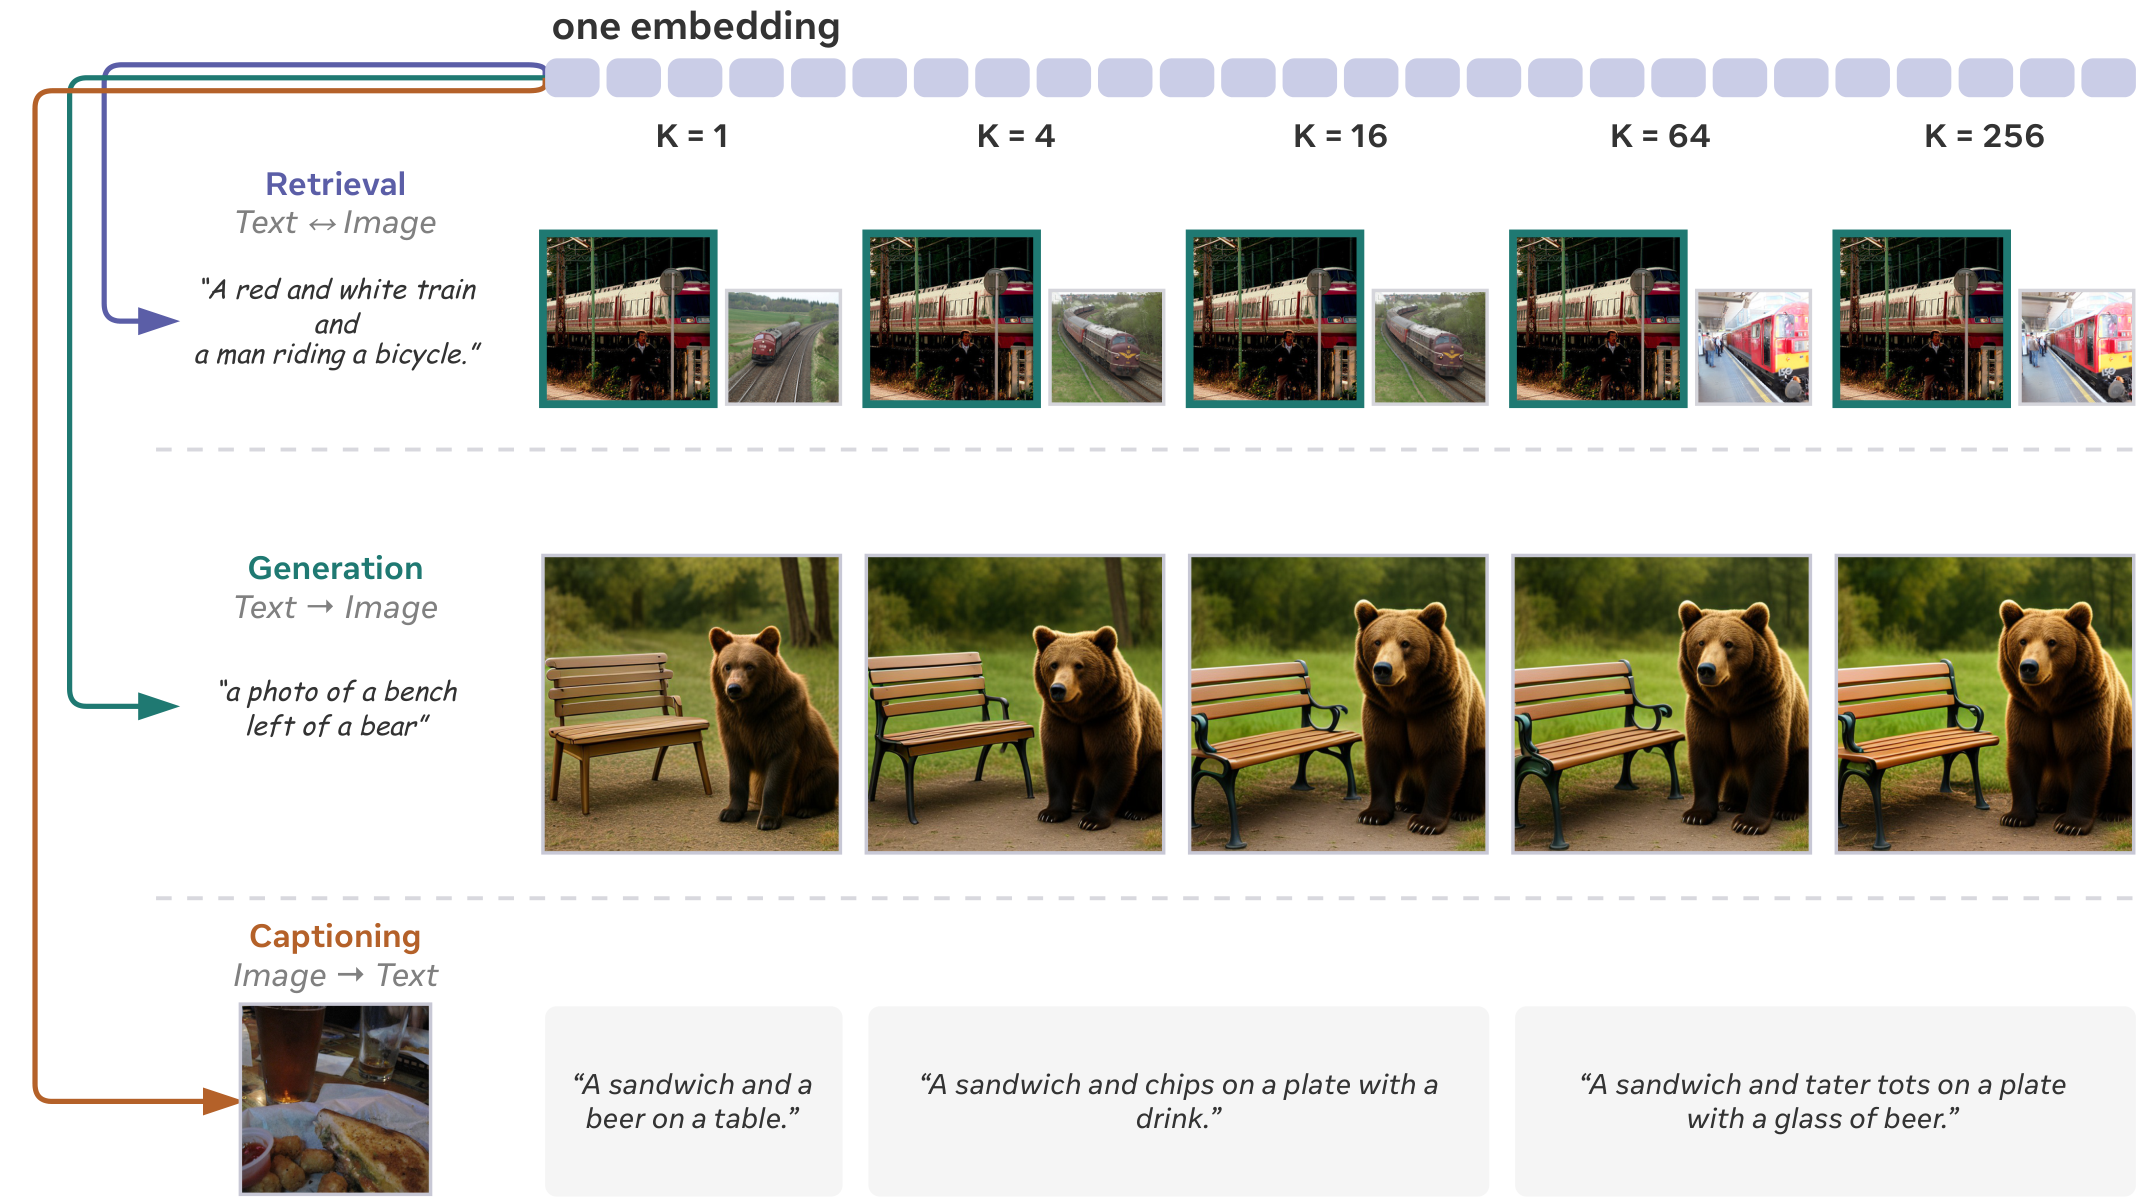
One representation, multiple capabilities. FLAT maps images and text into a shared sequence of continuous tokens. Any prefix can serve as a retrieval embedding or condition bidirectional generation.

Summary

Modern multimodal systems usually maintain separate representations for understanding and generation. FLAT instead resamples either images or text into the same one-dimensional sequence of continuous tokens, jointly trained for cross-modal alignment, image synthesis, and captioning.

Nested dropout organizes information from coarse to fine. At inference time, selecting a prefix of length K provides a direct compute–detail trade-off: the first token already captures global semantics, while longer prefixes recover composition and fine-grained attributes.
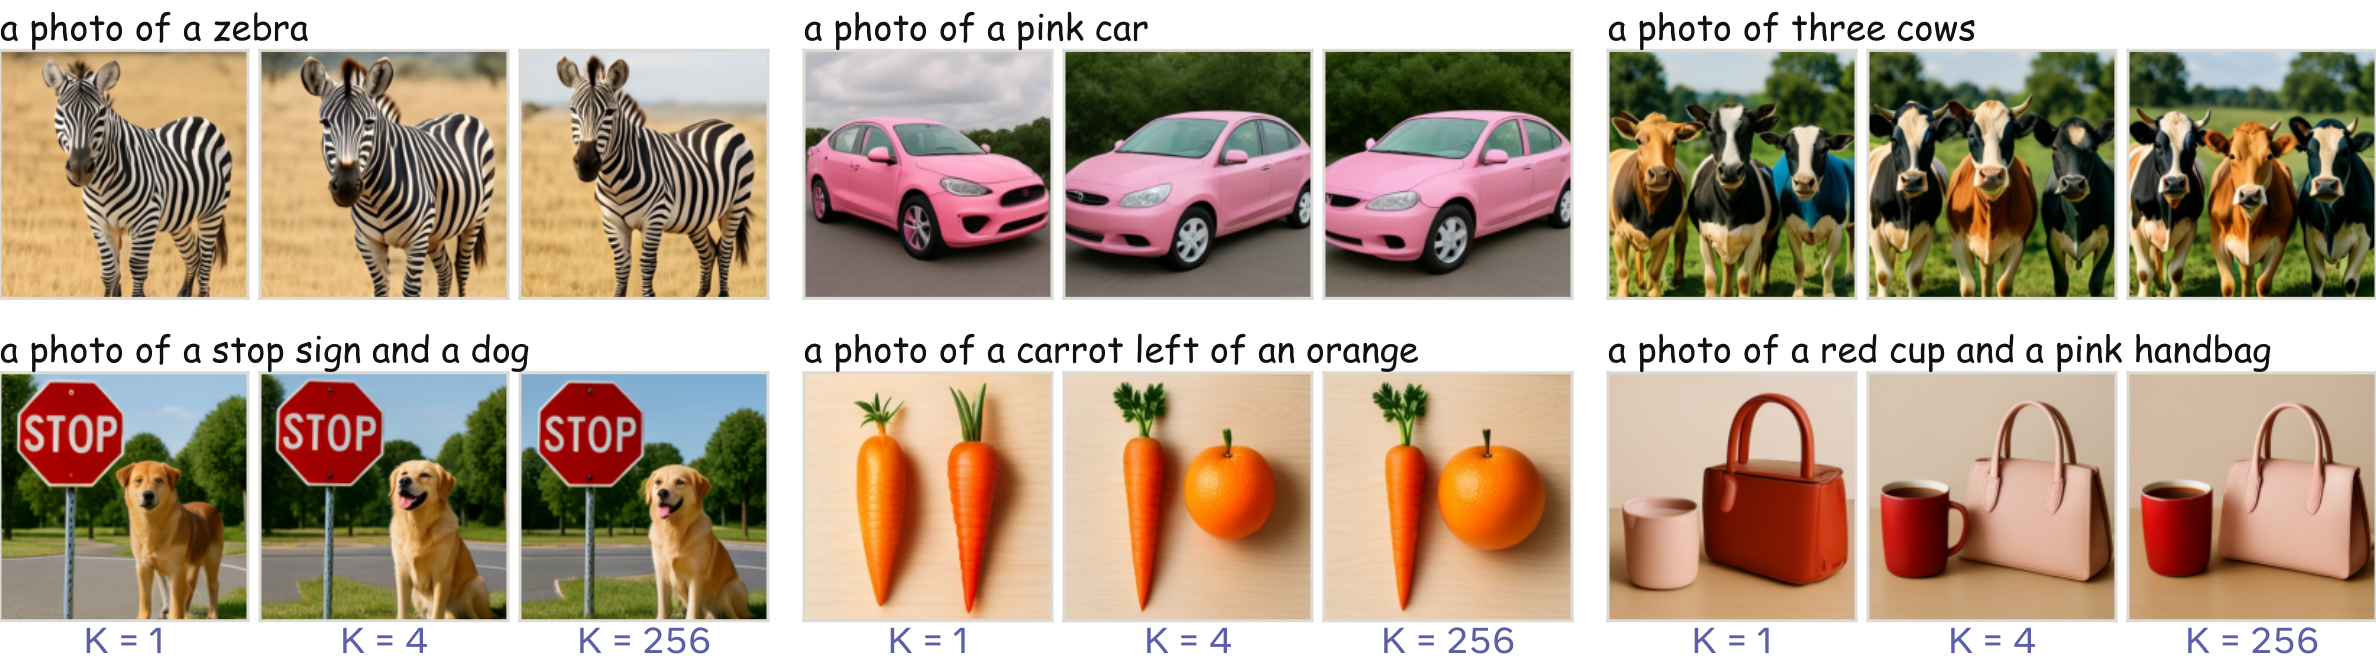
83.1GenEval
138.6COCO CIDEr
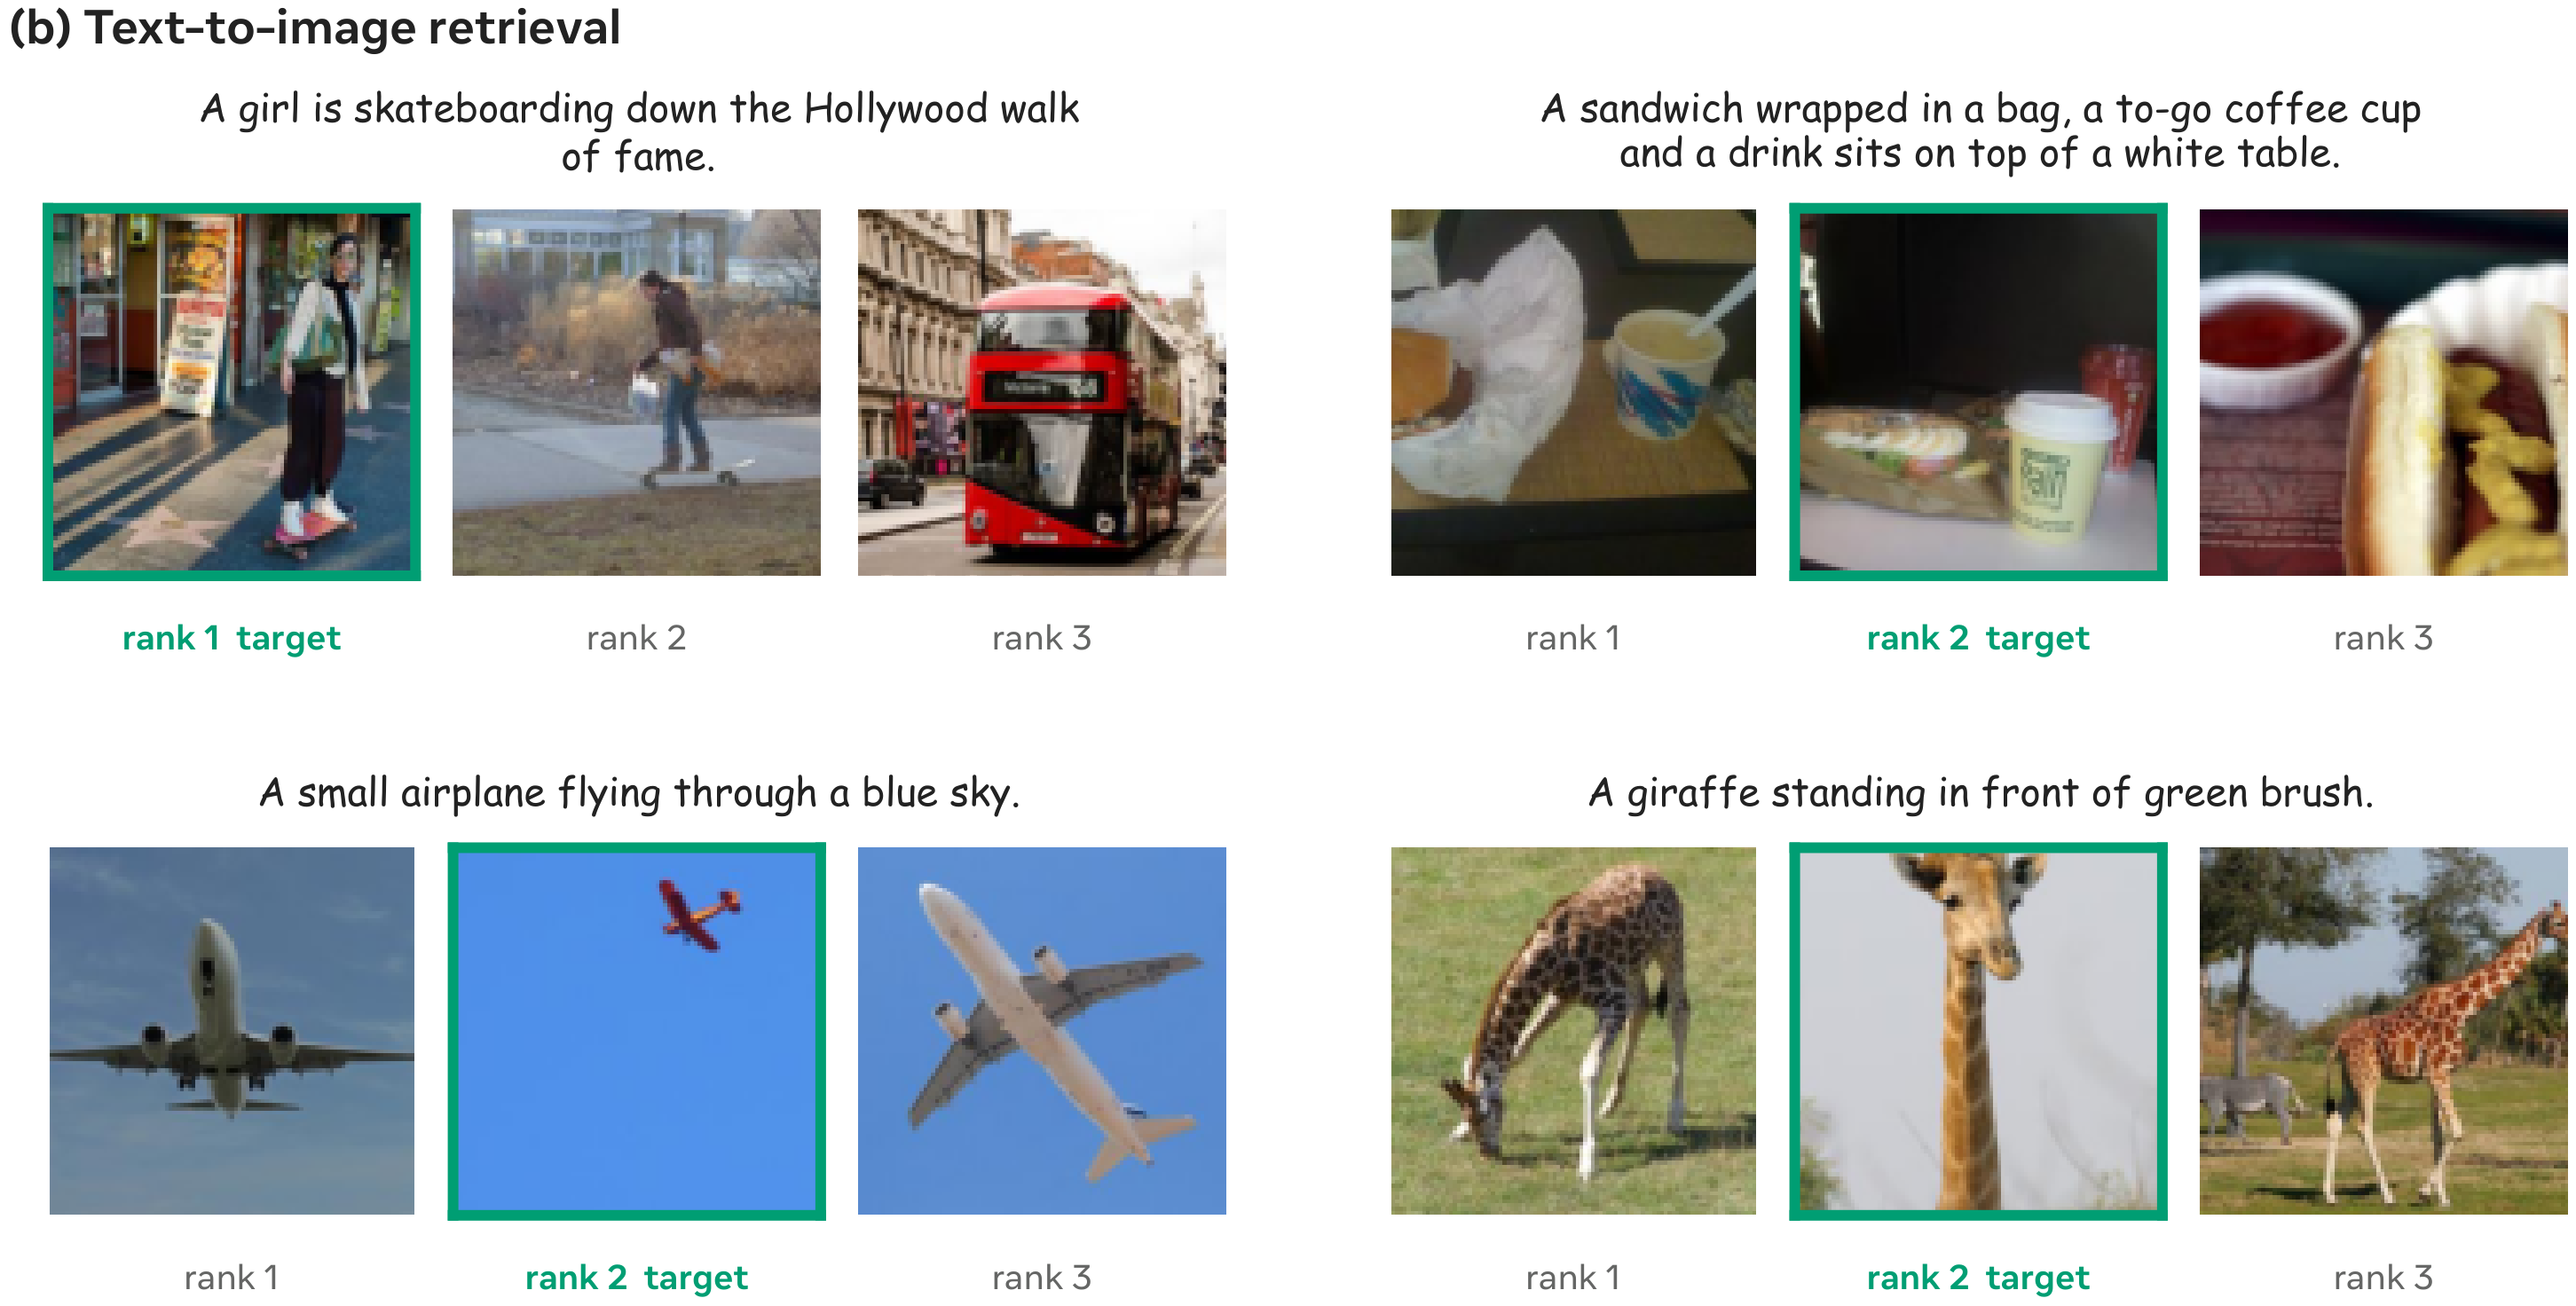
86.8 / 75.8COCO I2T / T2I R@5
98.3 / 93.6Flickr I2T / T2I R@5
81.8ImageNet linear probe
Architecture

A shared, ordered token space

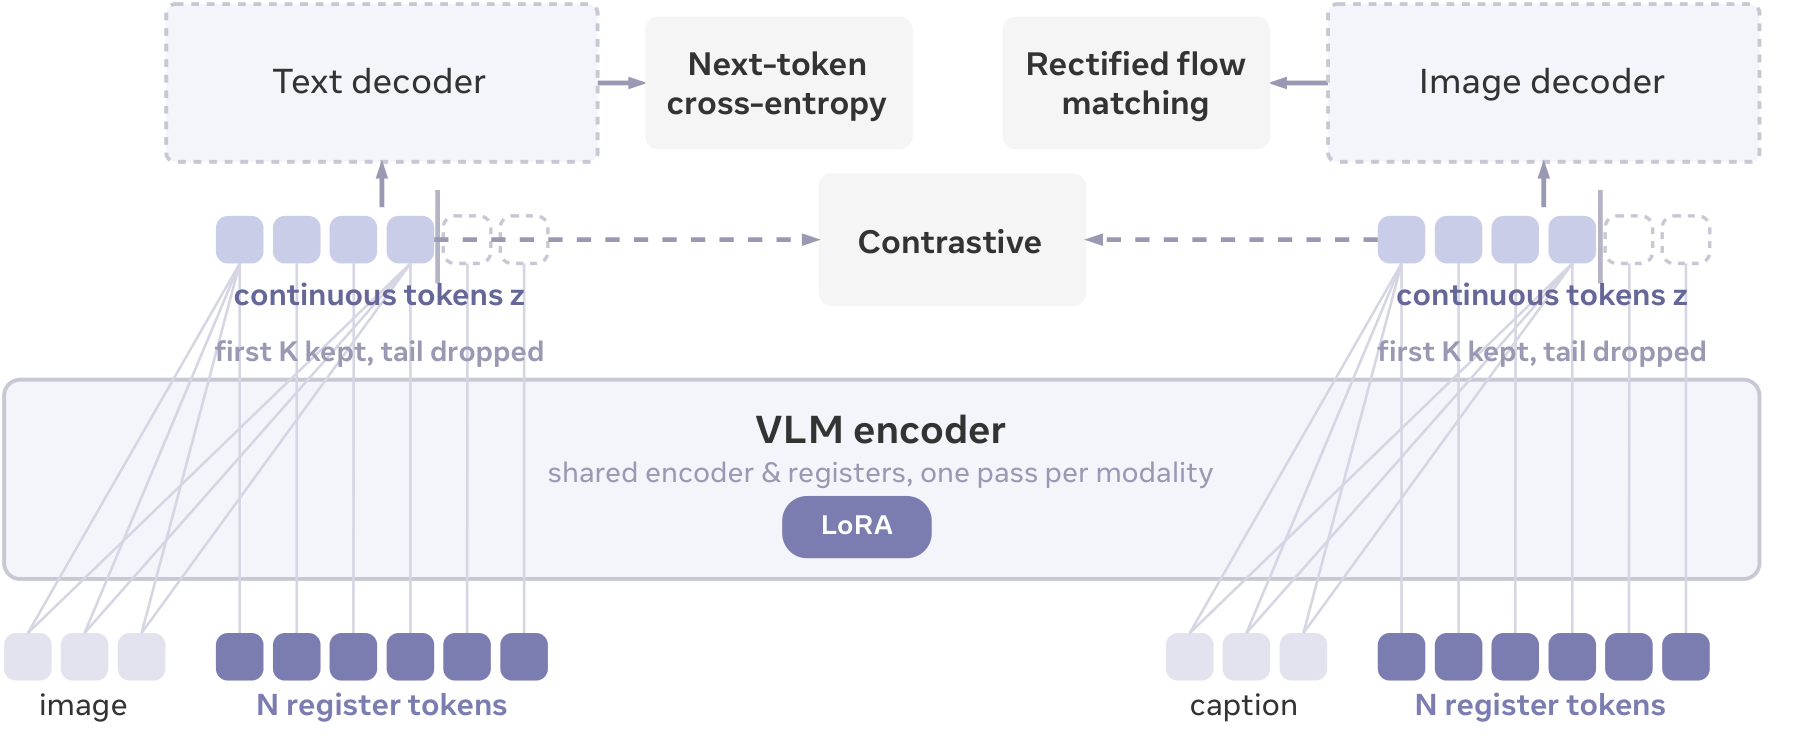
A single VLM encoder produces up to 256 continuous 64-dimensional register tokens for either modality.

FLAT architecture with a shared encoder, register tokens, and three training objectives.
The shared encoder resamples images and captions into aligned register tokens. Contrastive alignment and bidirectional generation jointly shape the latent space; nested dropout trains every prefix to remain useful.
Interactive static demo

One prefix, two decoded views

Move the slider to vary the number of active FLAT tokens, then compare how the same ordered representation supports generation, captioning, interpolation, and arithmetic.

Example
Loading examples…
FLAT · continuous
Active prefix length K = 1 · 64 dimensions
Loading precomputed outputs…

Loading precomputed outputs…

Generation

Coarse-to-fine decoding from any prefix

Increasing K adds compositional detail without switching representations or models.

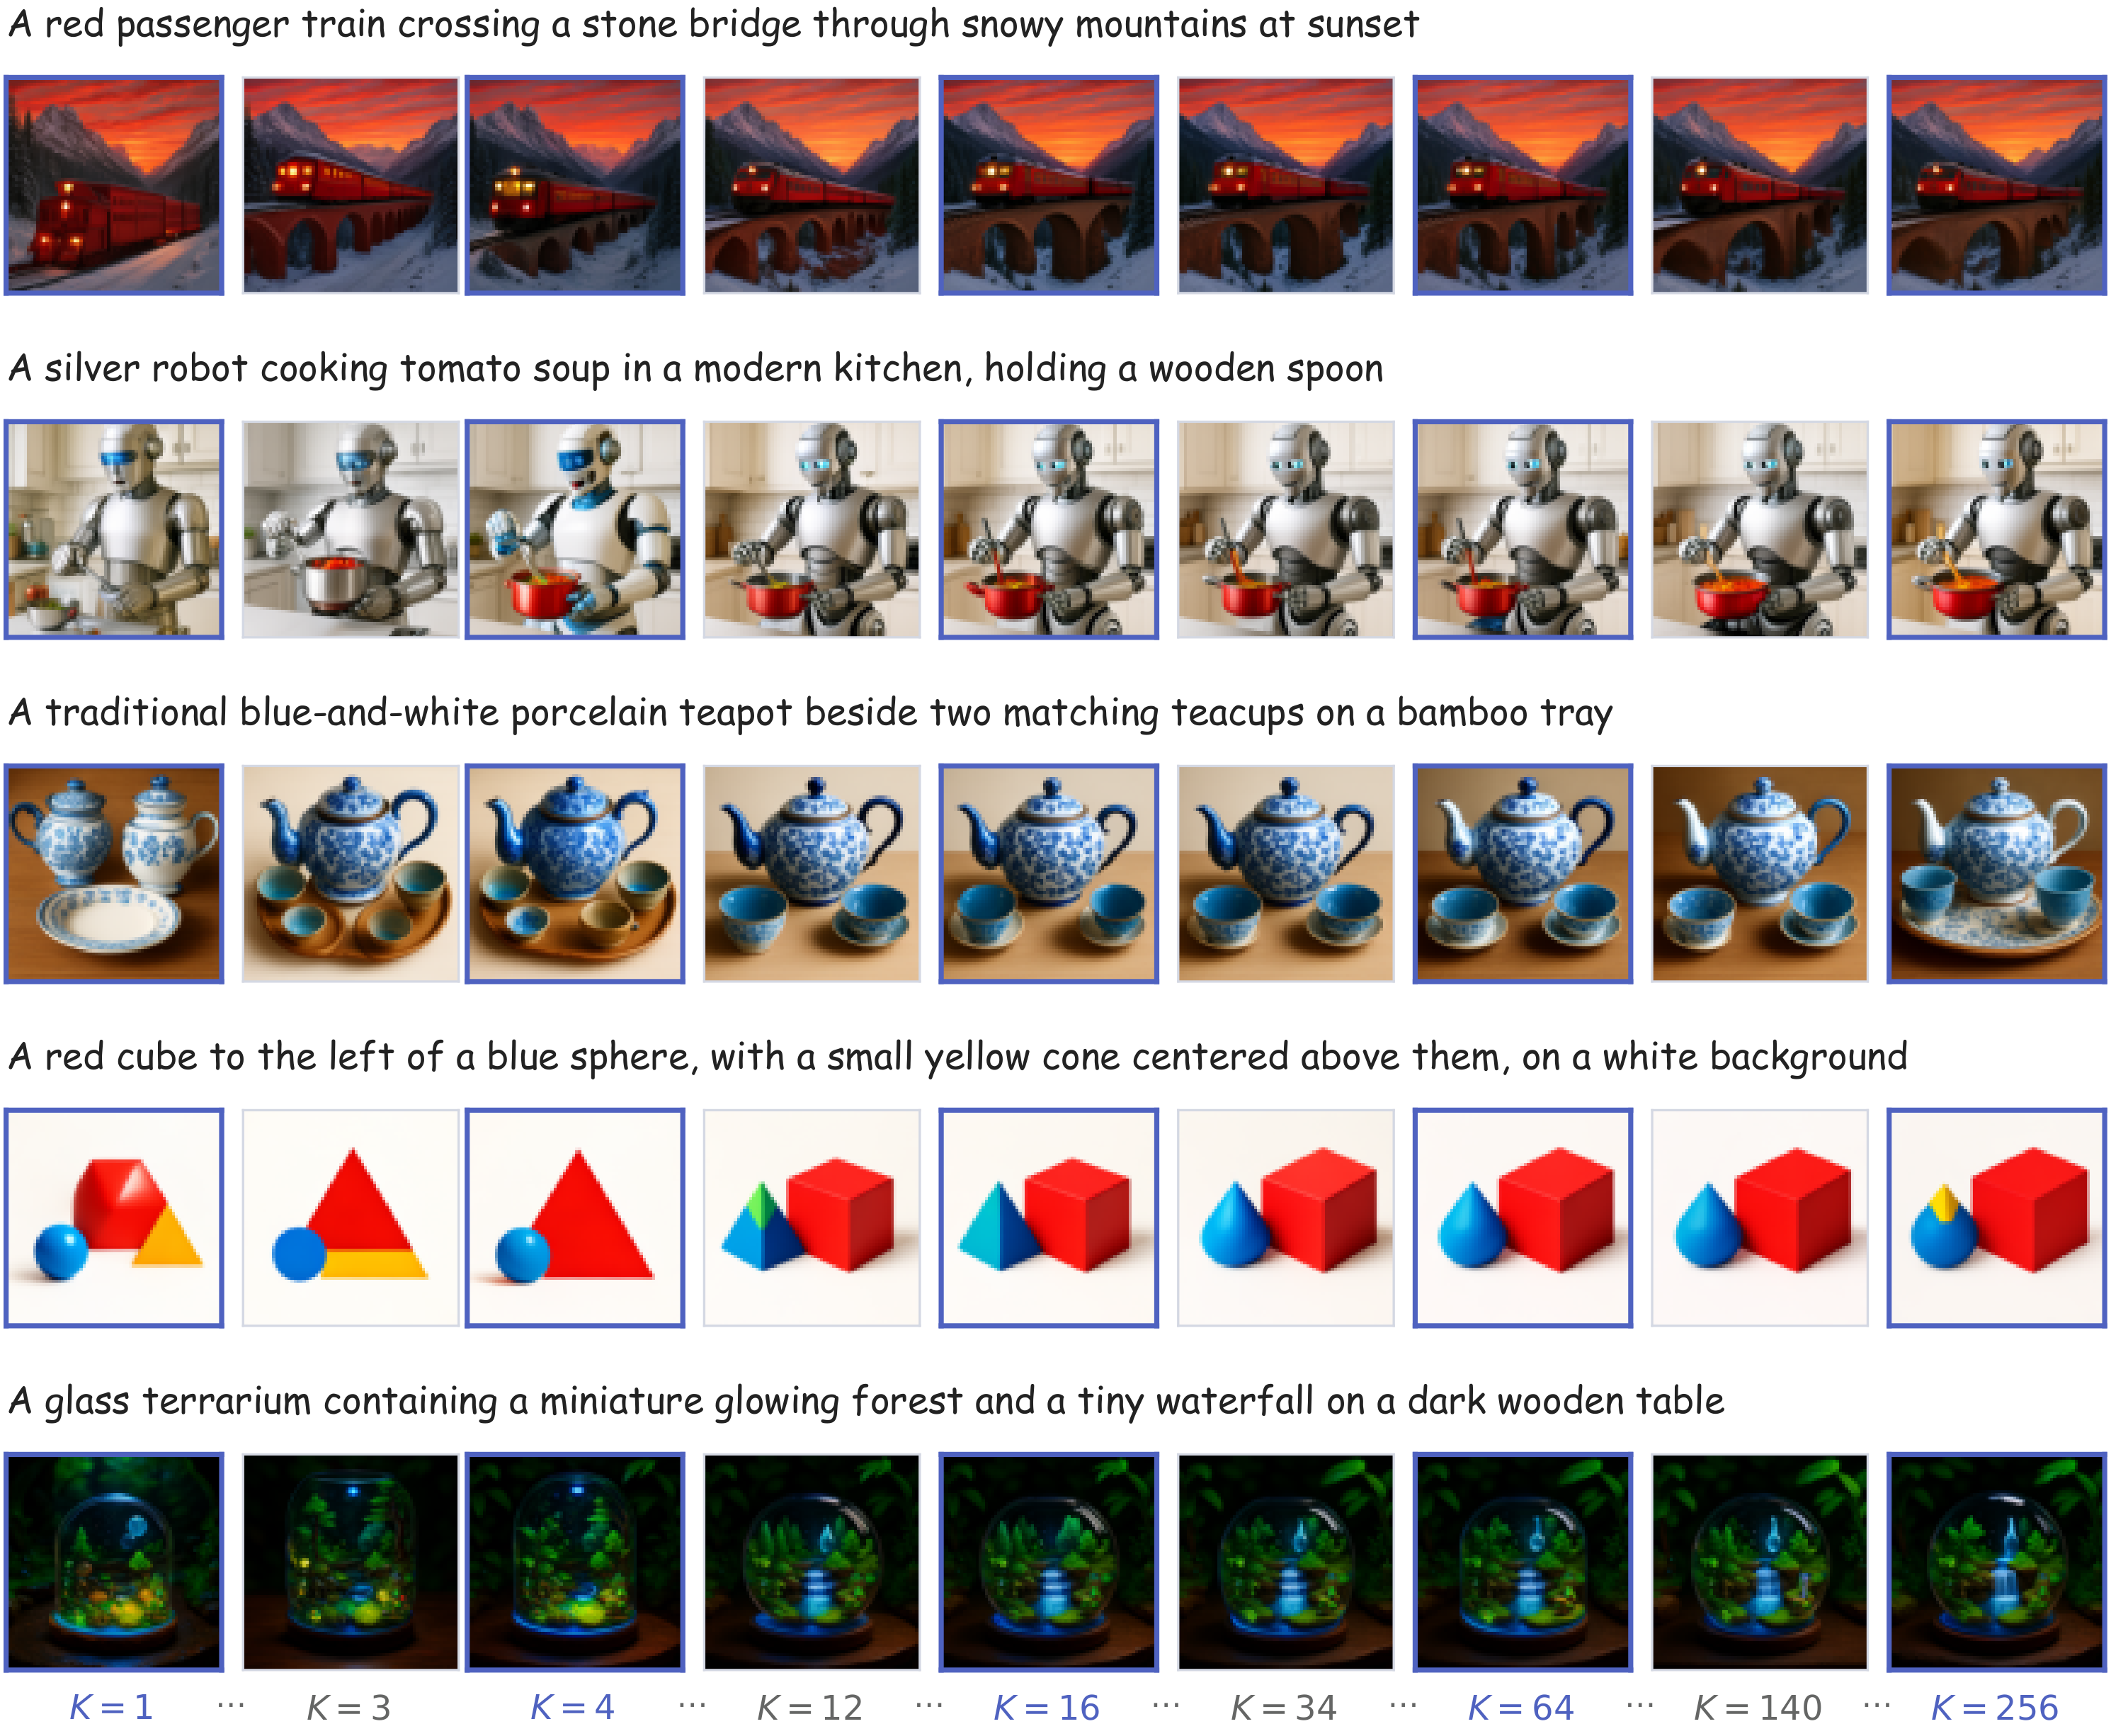
Text-to-image synthesis at K equals 1, 4, 16, 64, and 256.
Text-to-image synthesis. Short prefixes establish the principal concept; longer prefixes resolve counting, spatial relations, and attributes. The task-adapted model reaches 83.1 GenEval.

Image captioning

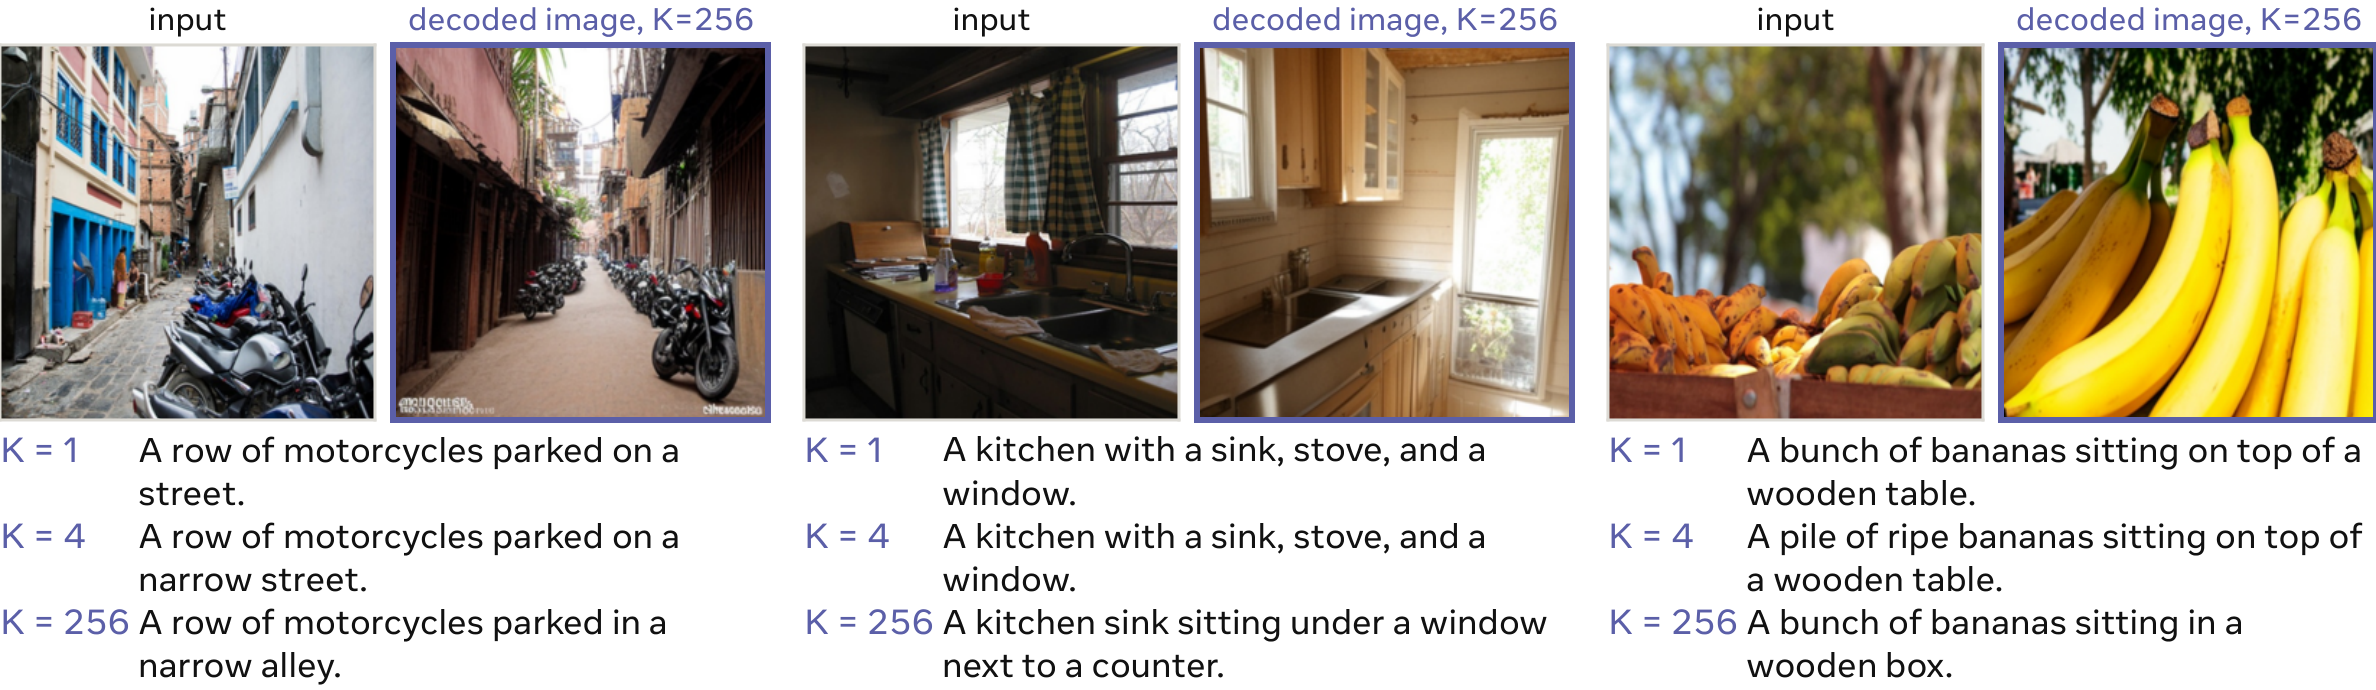
The same visual sequence conditions an autoregressive language decoder. Caption quality rises smoothly from K=1 to K=256, reaching 40.5 BLEU-4 and 138.6 CIDEr on COCO.

Image captioning examples across flexible prefix lengths.
Additional registers refine the description while preserving the main visual semantics captured by the earliest token.

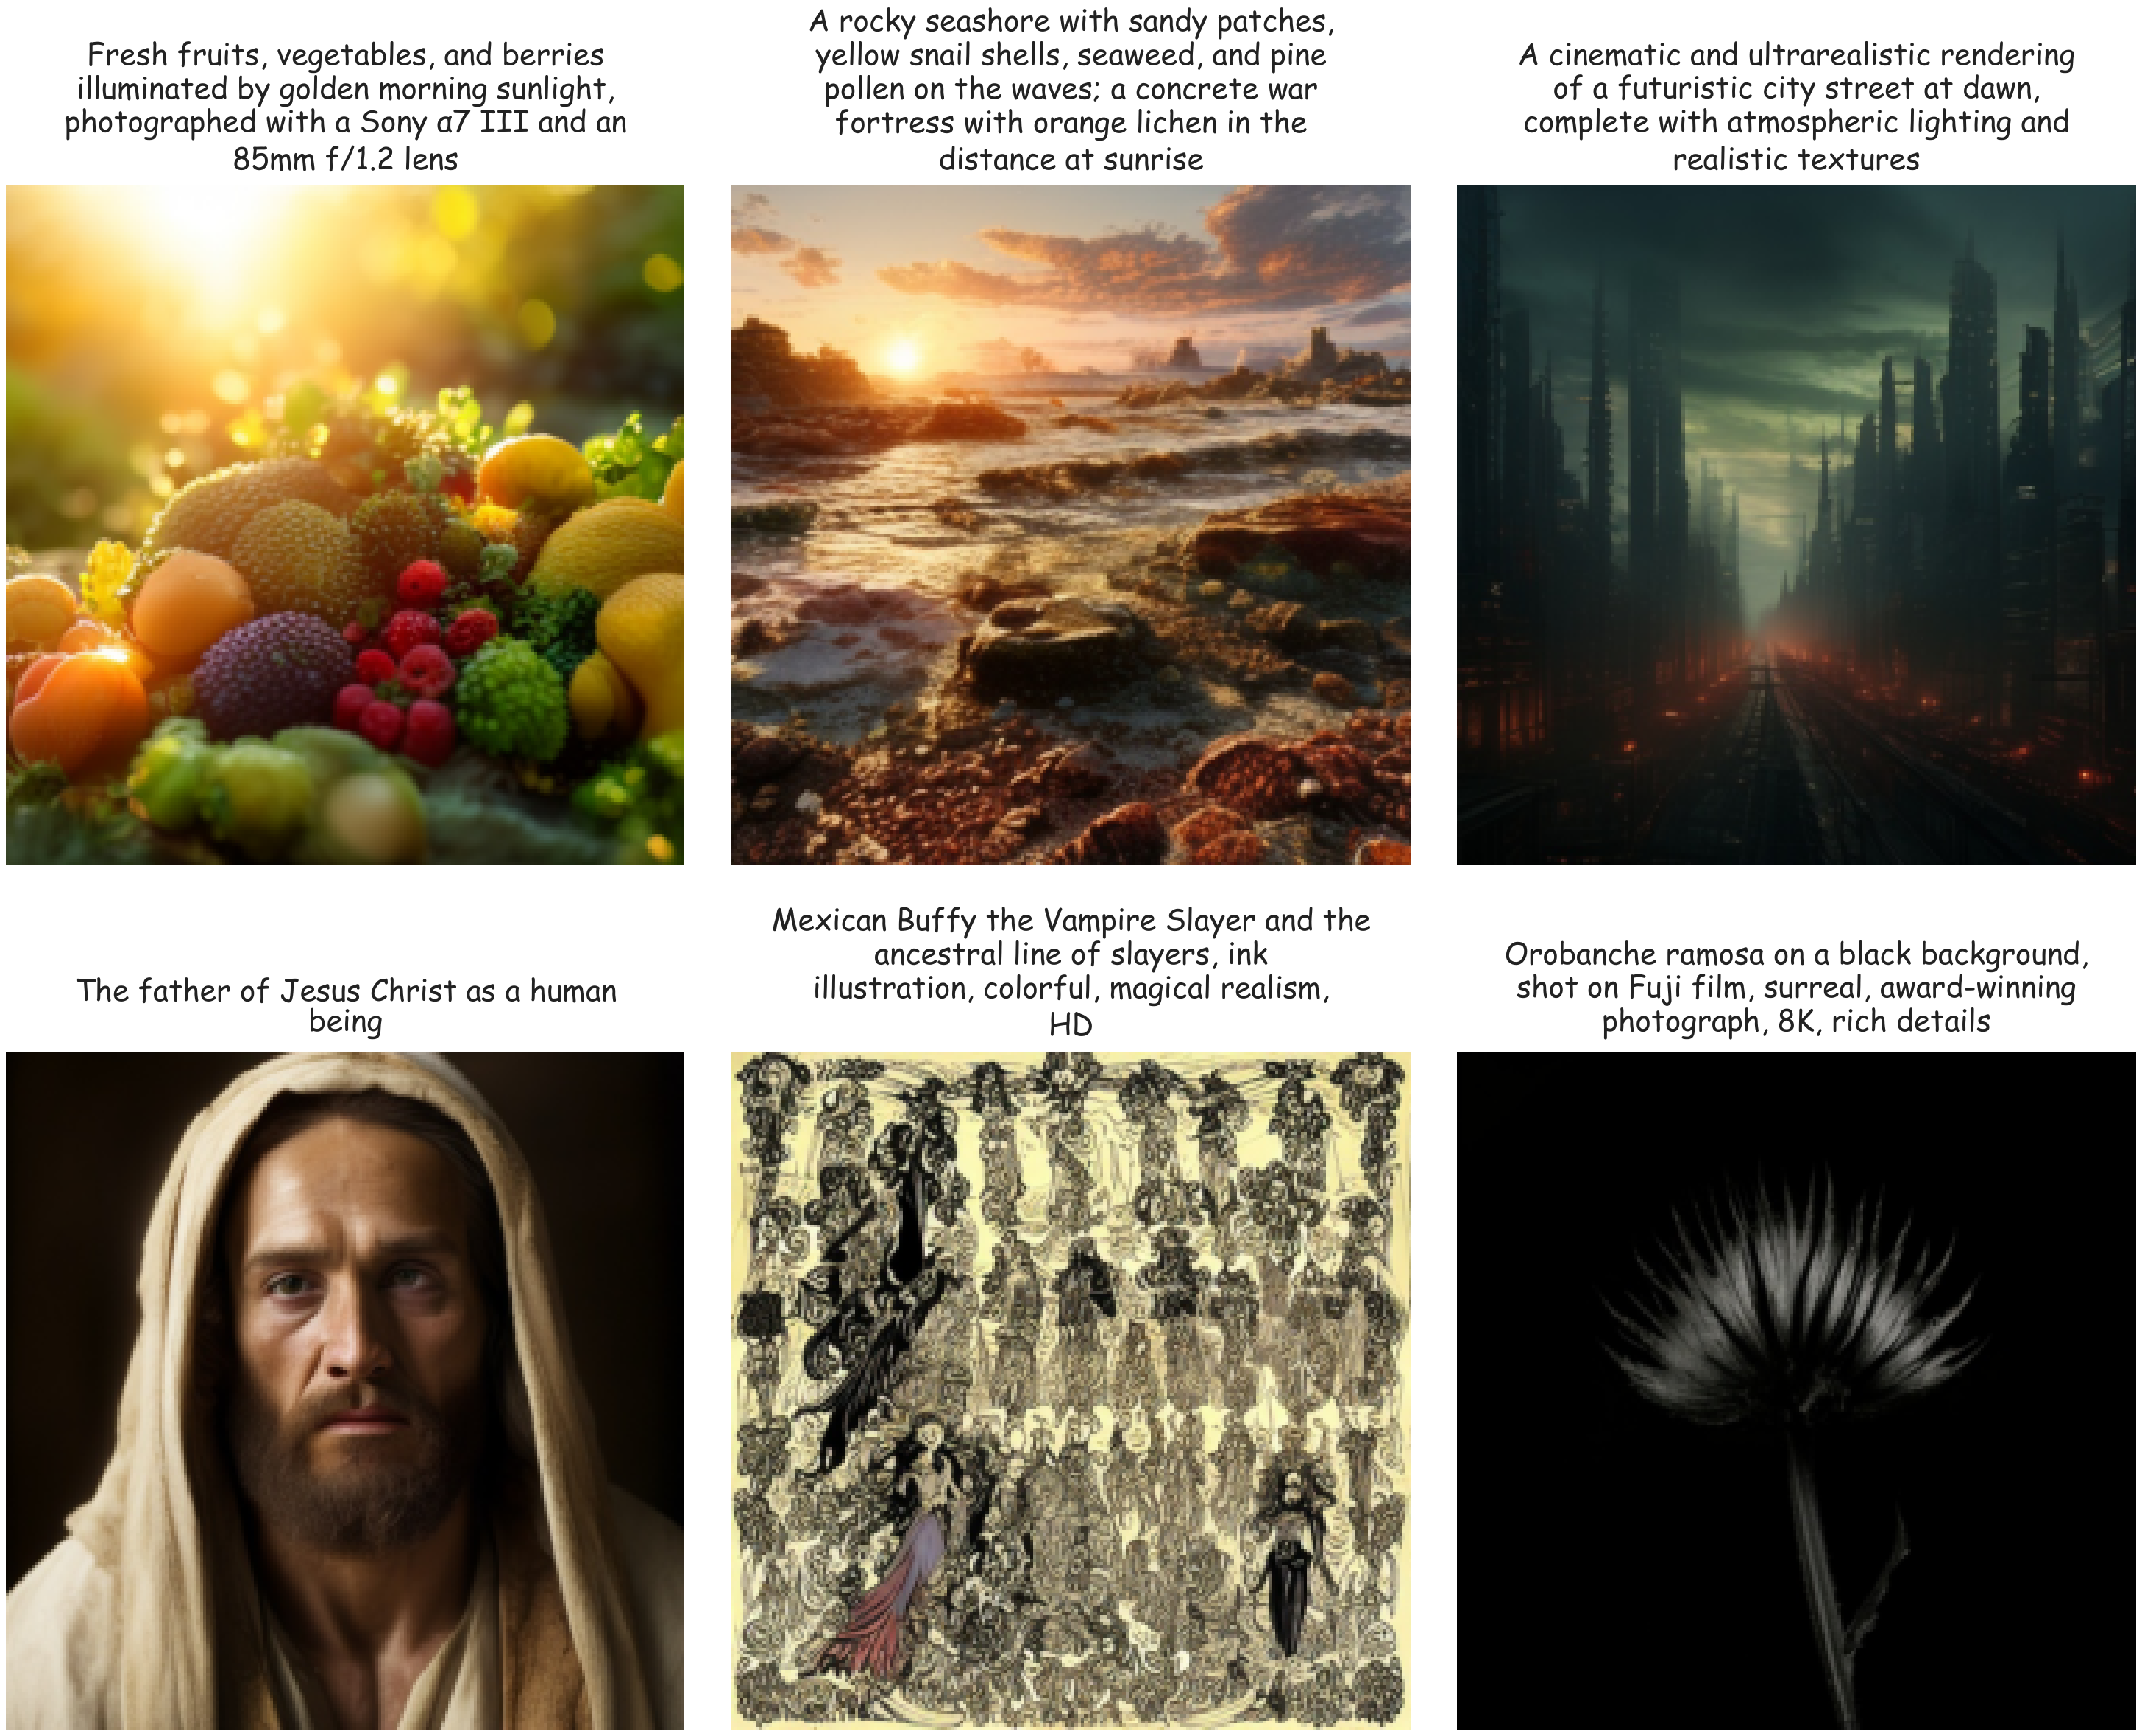
Complex text-to-image examples

Complex text-to-image examples generated by FLAT.
Qualitative generations cover detailed scenes, stylized compositions, portraits, and unusual concepts beyond the diagnostic GenEval prompts.
Retrieval

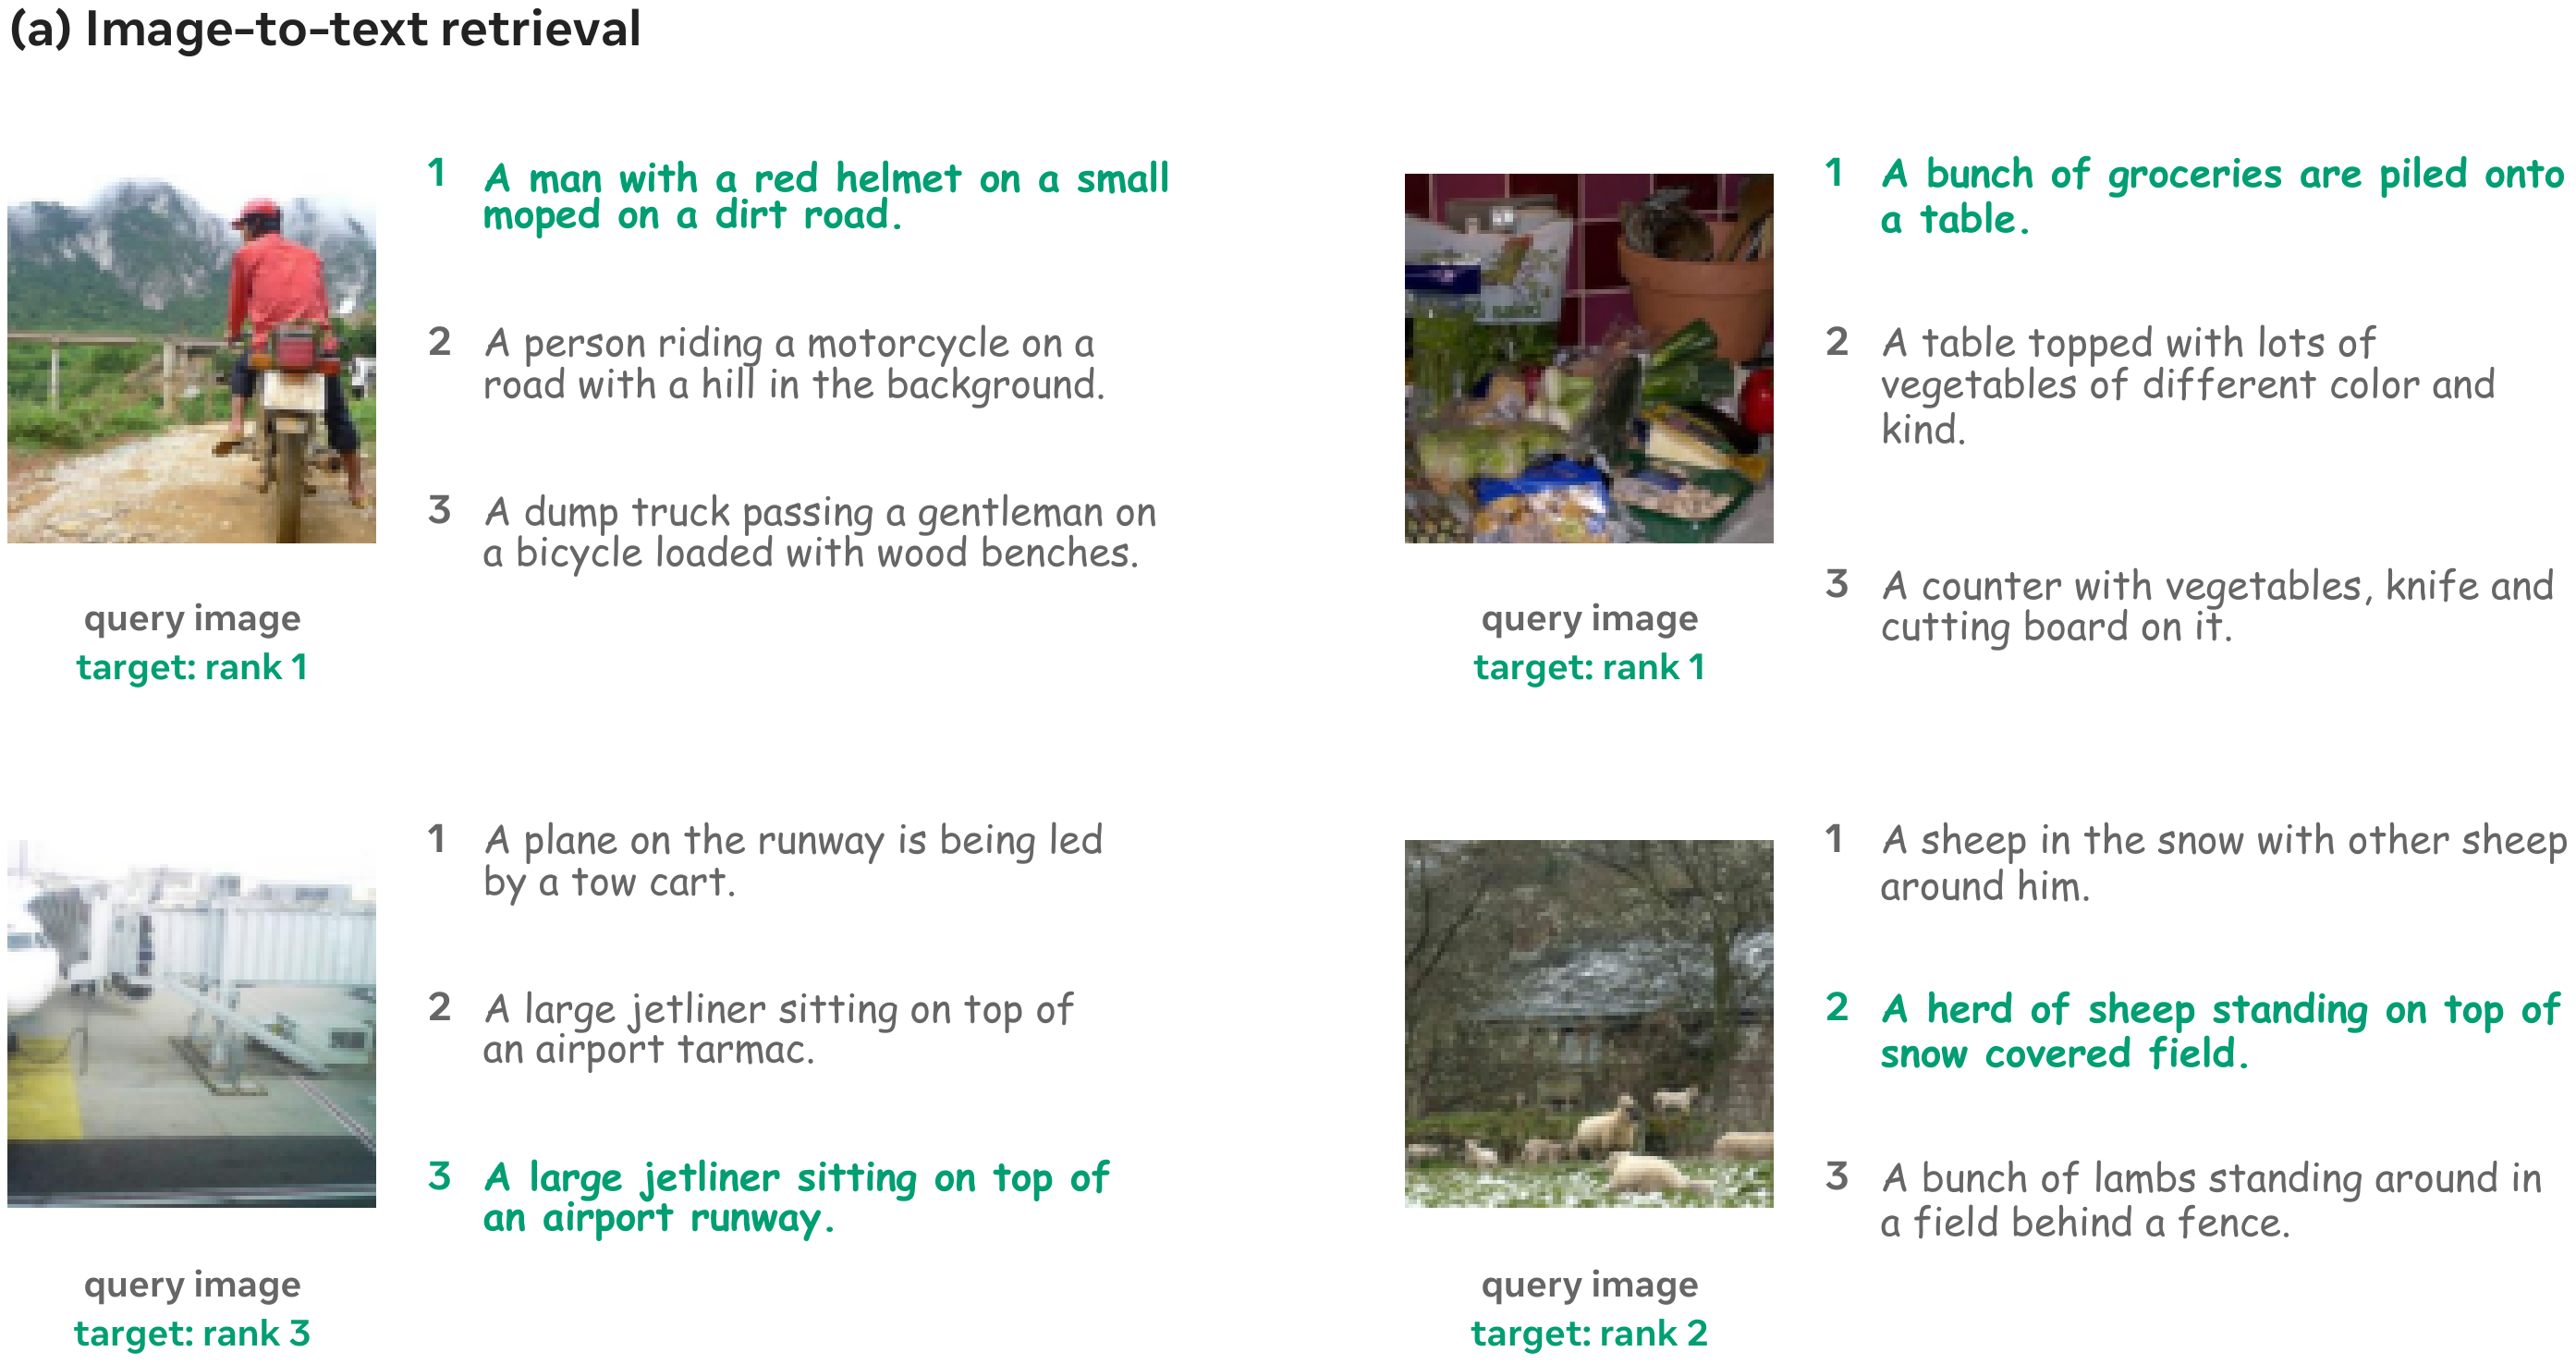
One token is already competitive

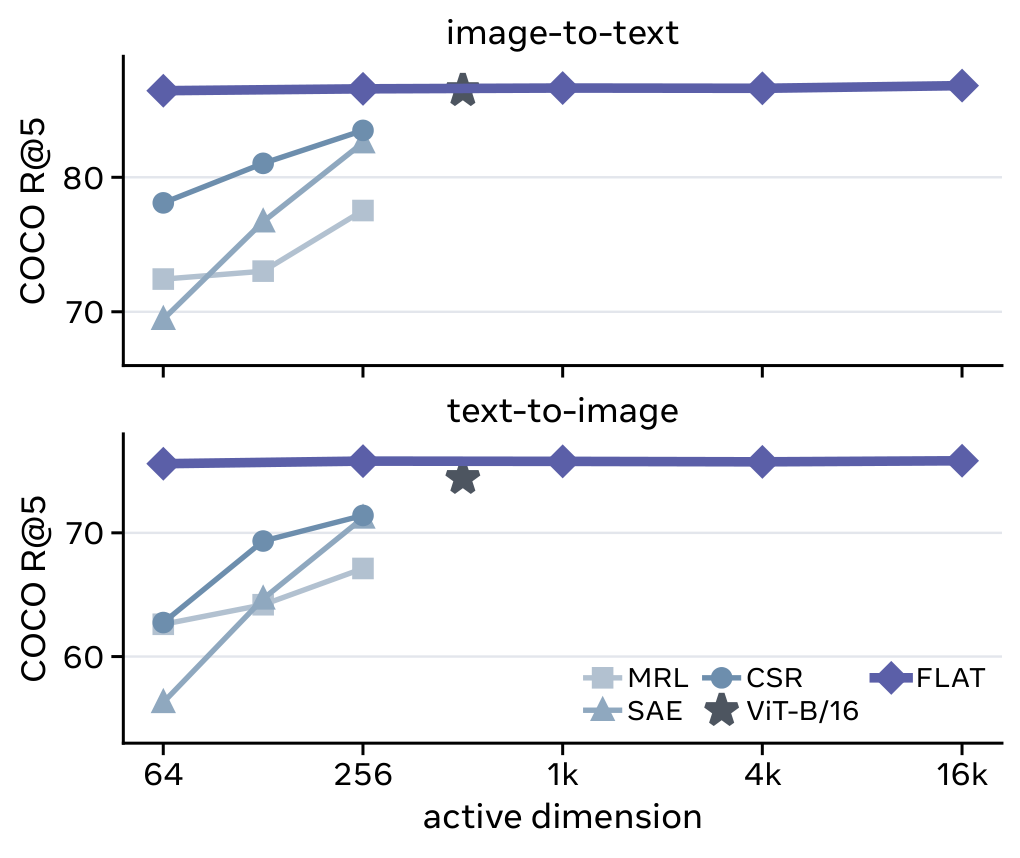
Retrieval remains nearly unchanged across a 256× range in representation width.

COCO retrieval recall across active dimensions compared with adaptive-width baselines.
COCO R@5 versus active dimensionality. Each FLAT token contributes 64 dimensions.
Dataset / KI→T R@1I→T R@5T→I R@1T→I R@5
COCO / 163.0086.4447.7675.59
COCO / 25663.5486.8247.9875.83
Flickr / 190.5098.1076.9493.52
Flickr / 491.2098.3077.4093.58

Across all reported recall metrics, moving from K=1 to K=256 changes COCO performance by less than one point.

Representation analysis

Aligned geometry with semantic structure

FLAT's continuous tokens are simultaneously cross-modal, discriminative, and decodable.

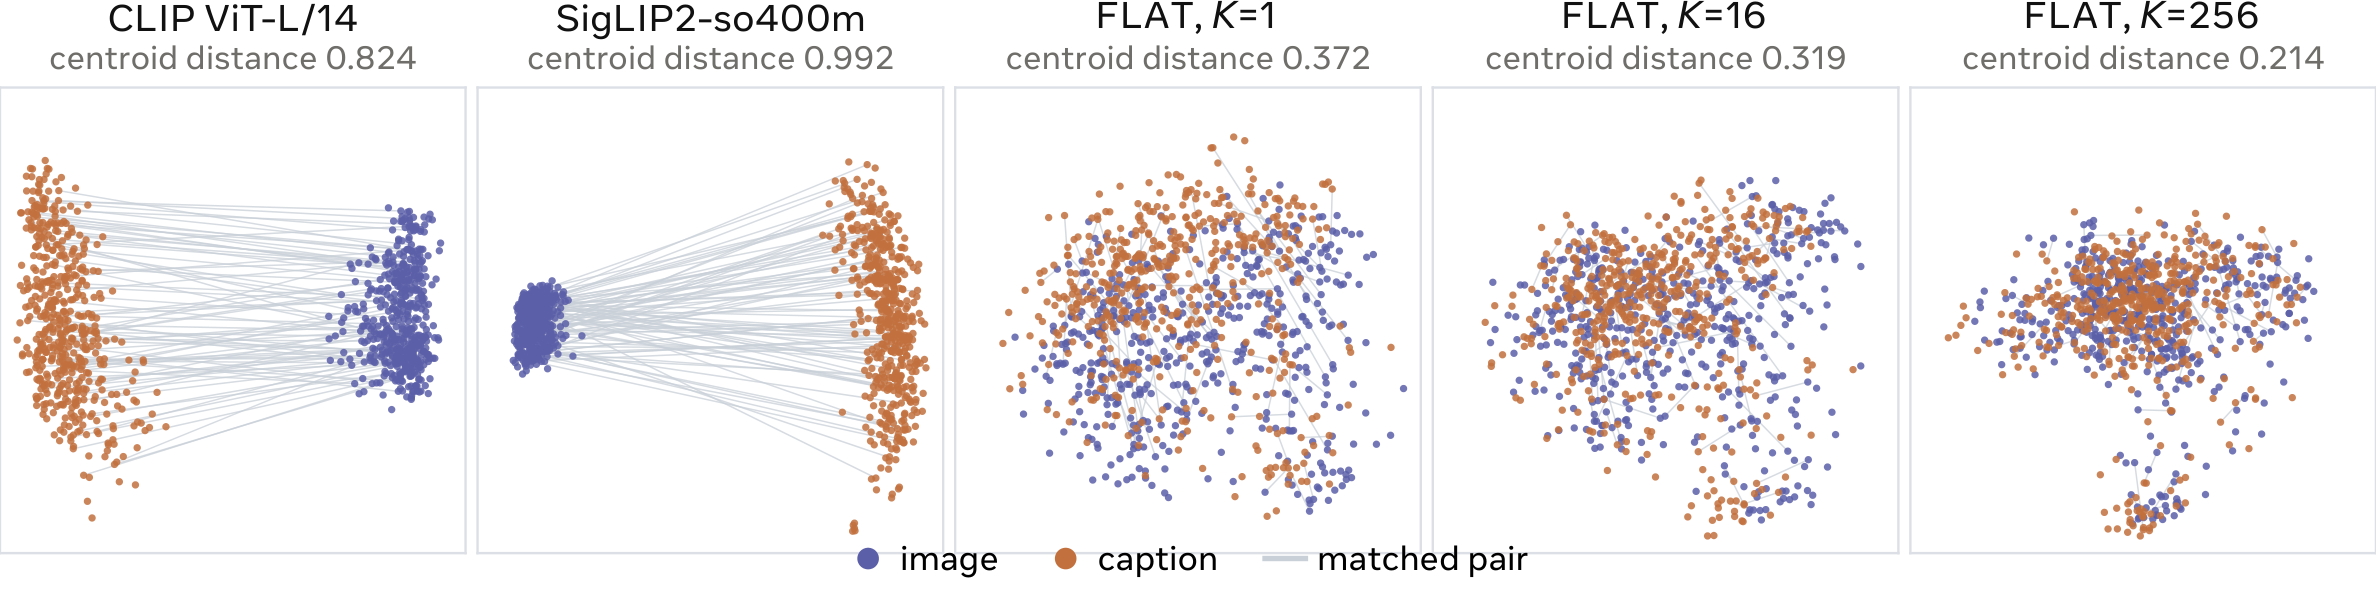
PCA distributions for matched image and text representations.
Closing the modality gap. A single FLAT token halves CLIP's image–text centroid distance; the full sequence reduces it to roughly one quarter.
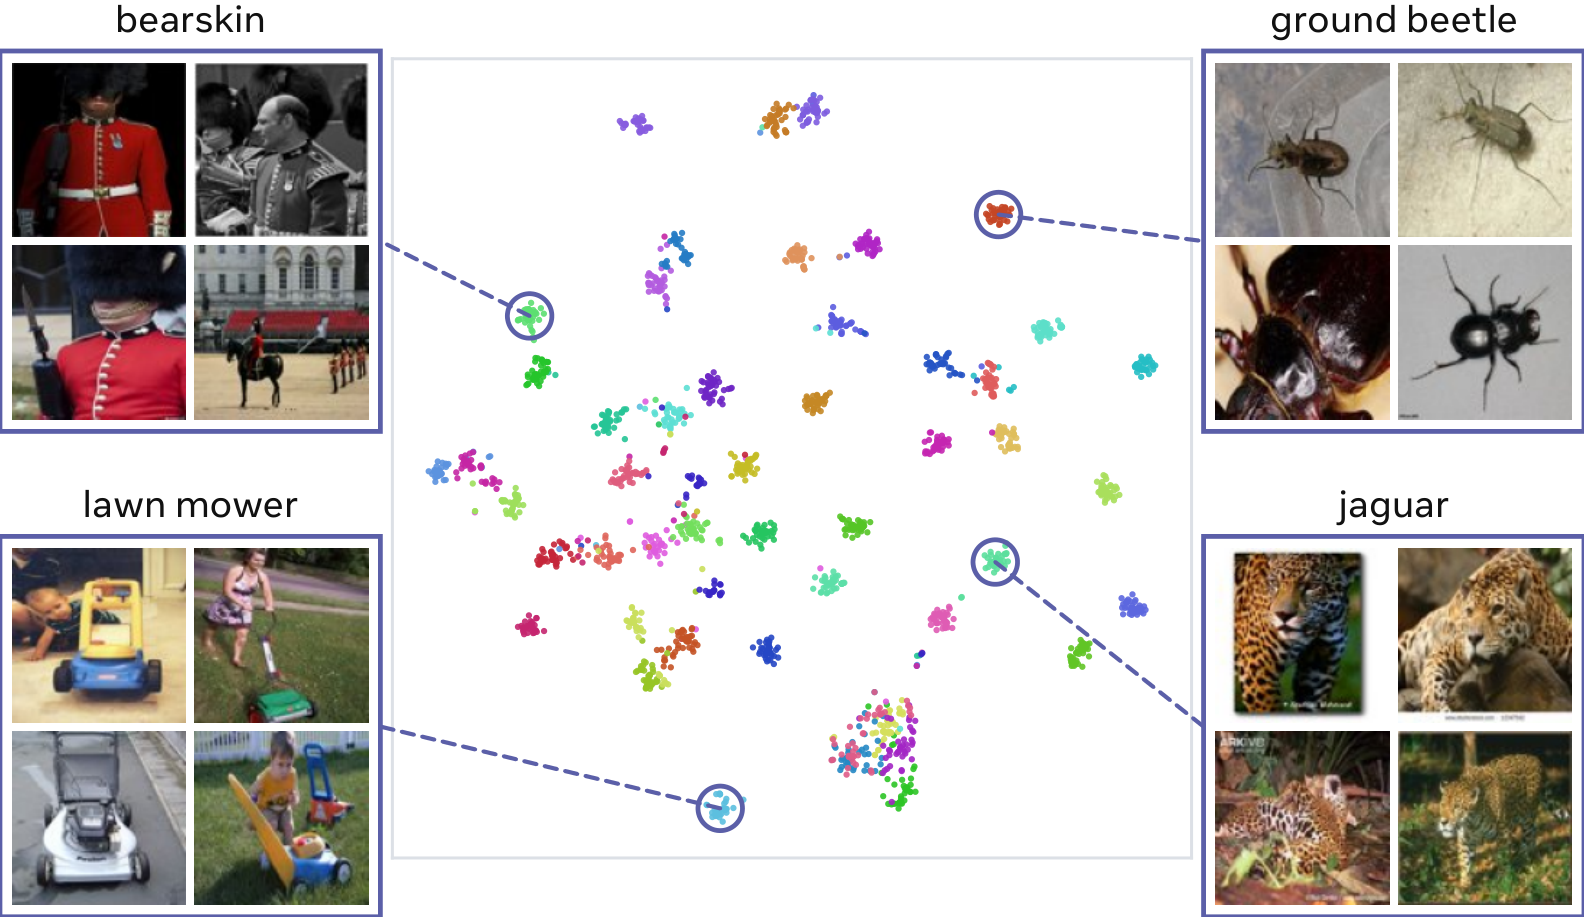
Unsupervised clustering of a single FLAT token.
Unsupervised structure. k-means over the frozen 64-D K=1 token recovers visually coherent ImageNet categories.

Linear probing

A linear classifier on frozen FLAT features reaches 73.3% ImageNet-1K top-1 with one 64-D token, 81.2% with 16 tokens, and 81.8% with 64 tokens.

KDimensionsTop-1
16473.3
425677.0
161,02481.2
644,09681.8
25616,38481.8

Continuous latent operations

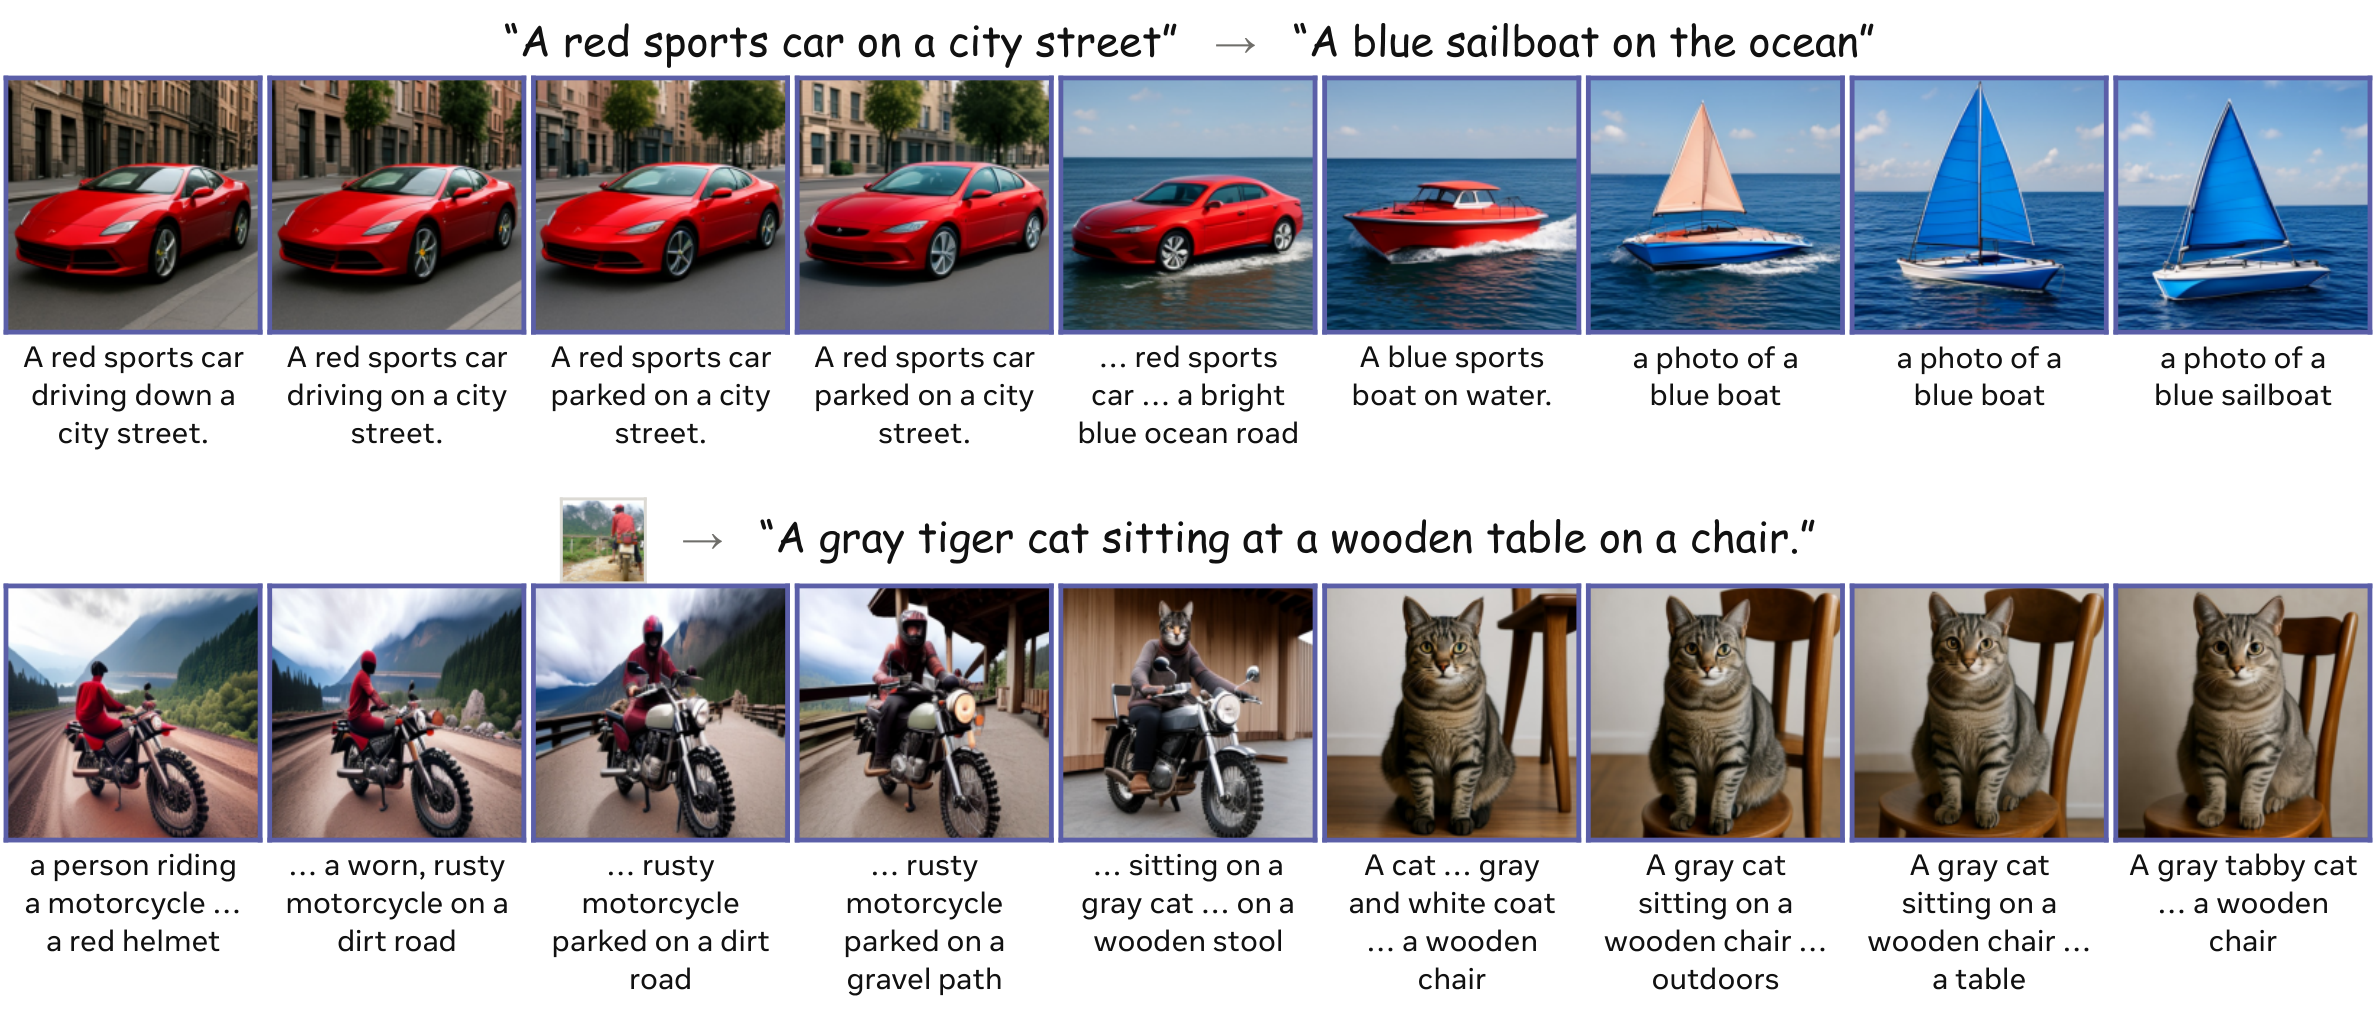
Because image and text occupy a shared decodable space, simple vector operations produce interpretable semantic transitions.

Continuous cross-modal interpolation between image and text concepts.
Interpolation. Image and text decoders follow corresponding intermediate concepts along the same latent trajectory.
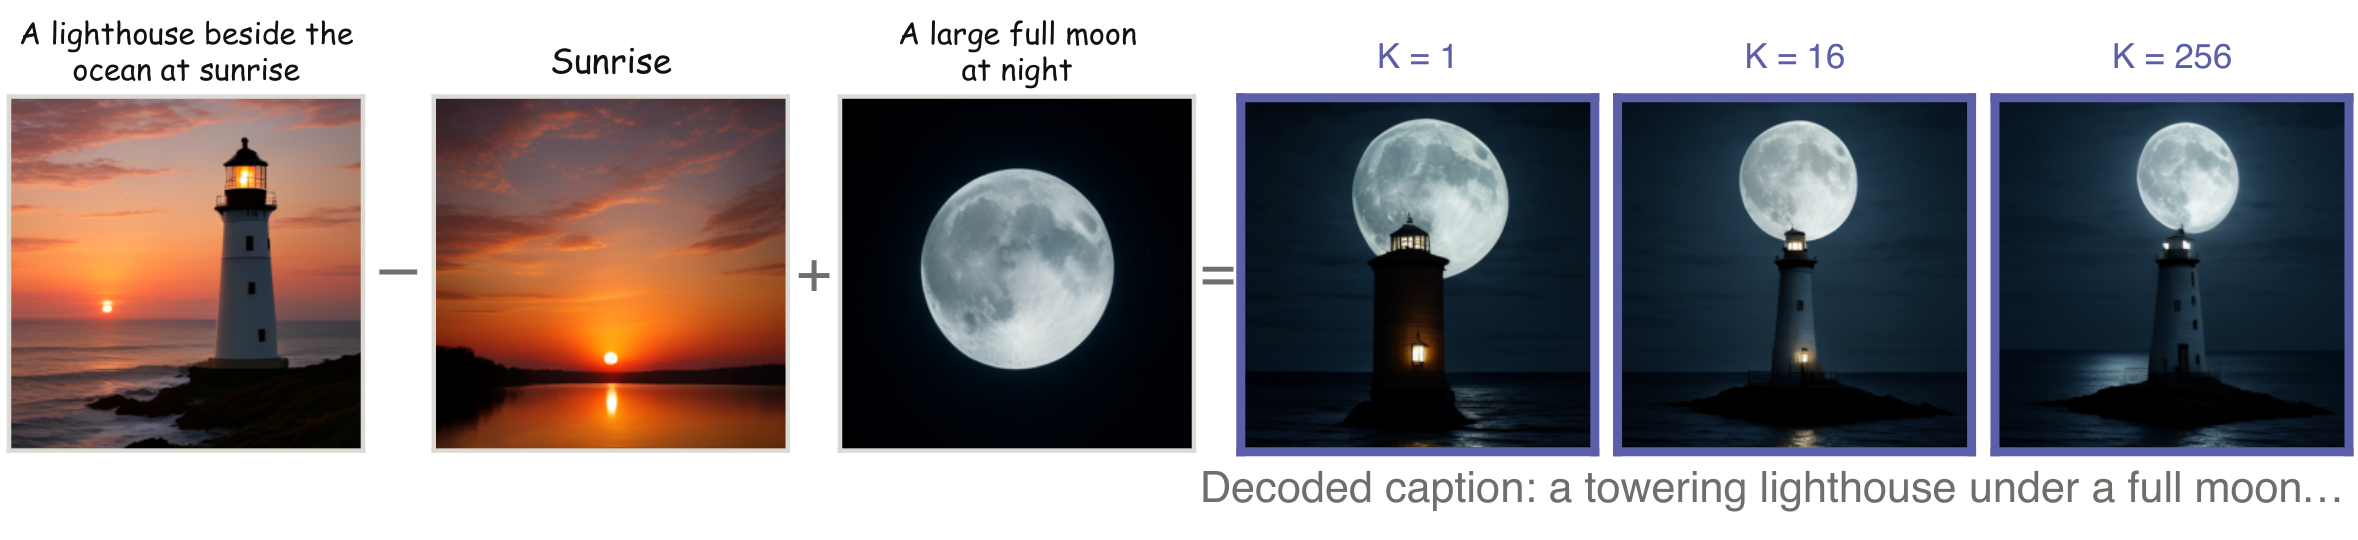
Token arithmetic combining a lighthouse and a full moon.
Semantic arithmetic. Token-wise composition adds the semantics of a full moon to a lighthouse scene; larger prefixes preserve increasingly detailed structure.
Beyond paired image–English training

Zero-shot transfer

The shared VLM encoder exposes capabilities that were not explicitly supervised by the training mixture.

Multilingual and symbolic inputs

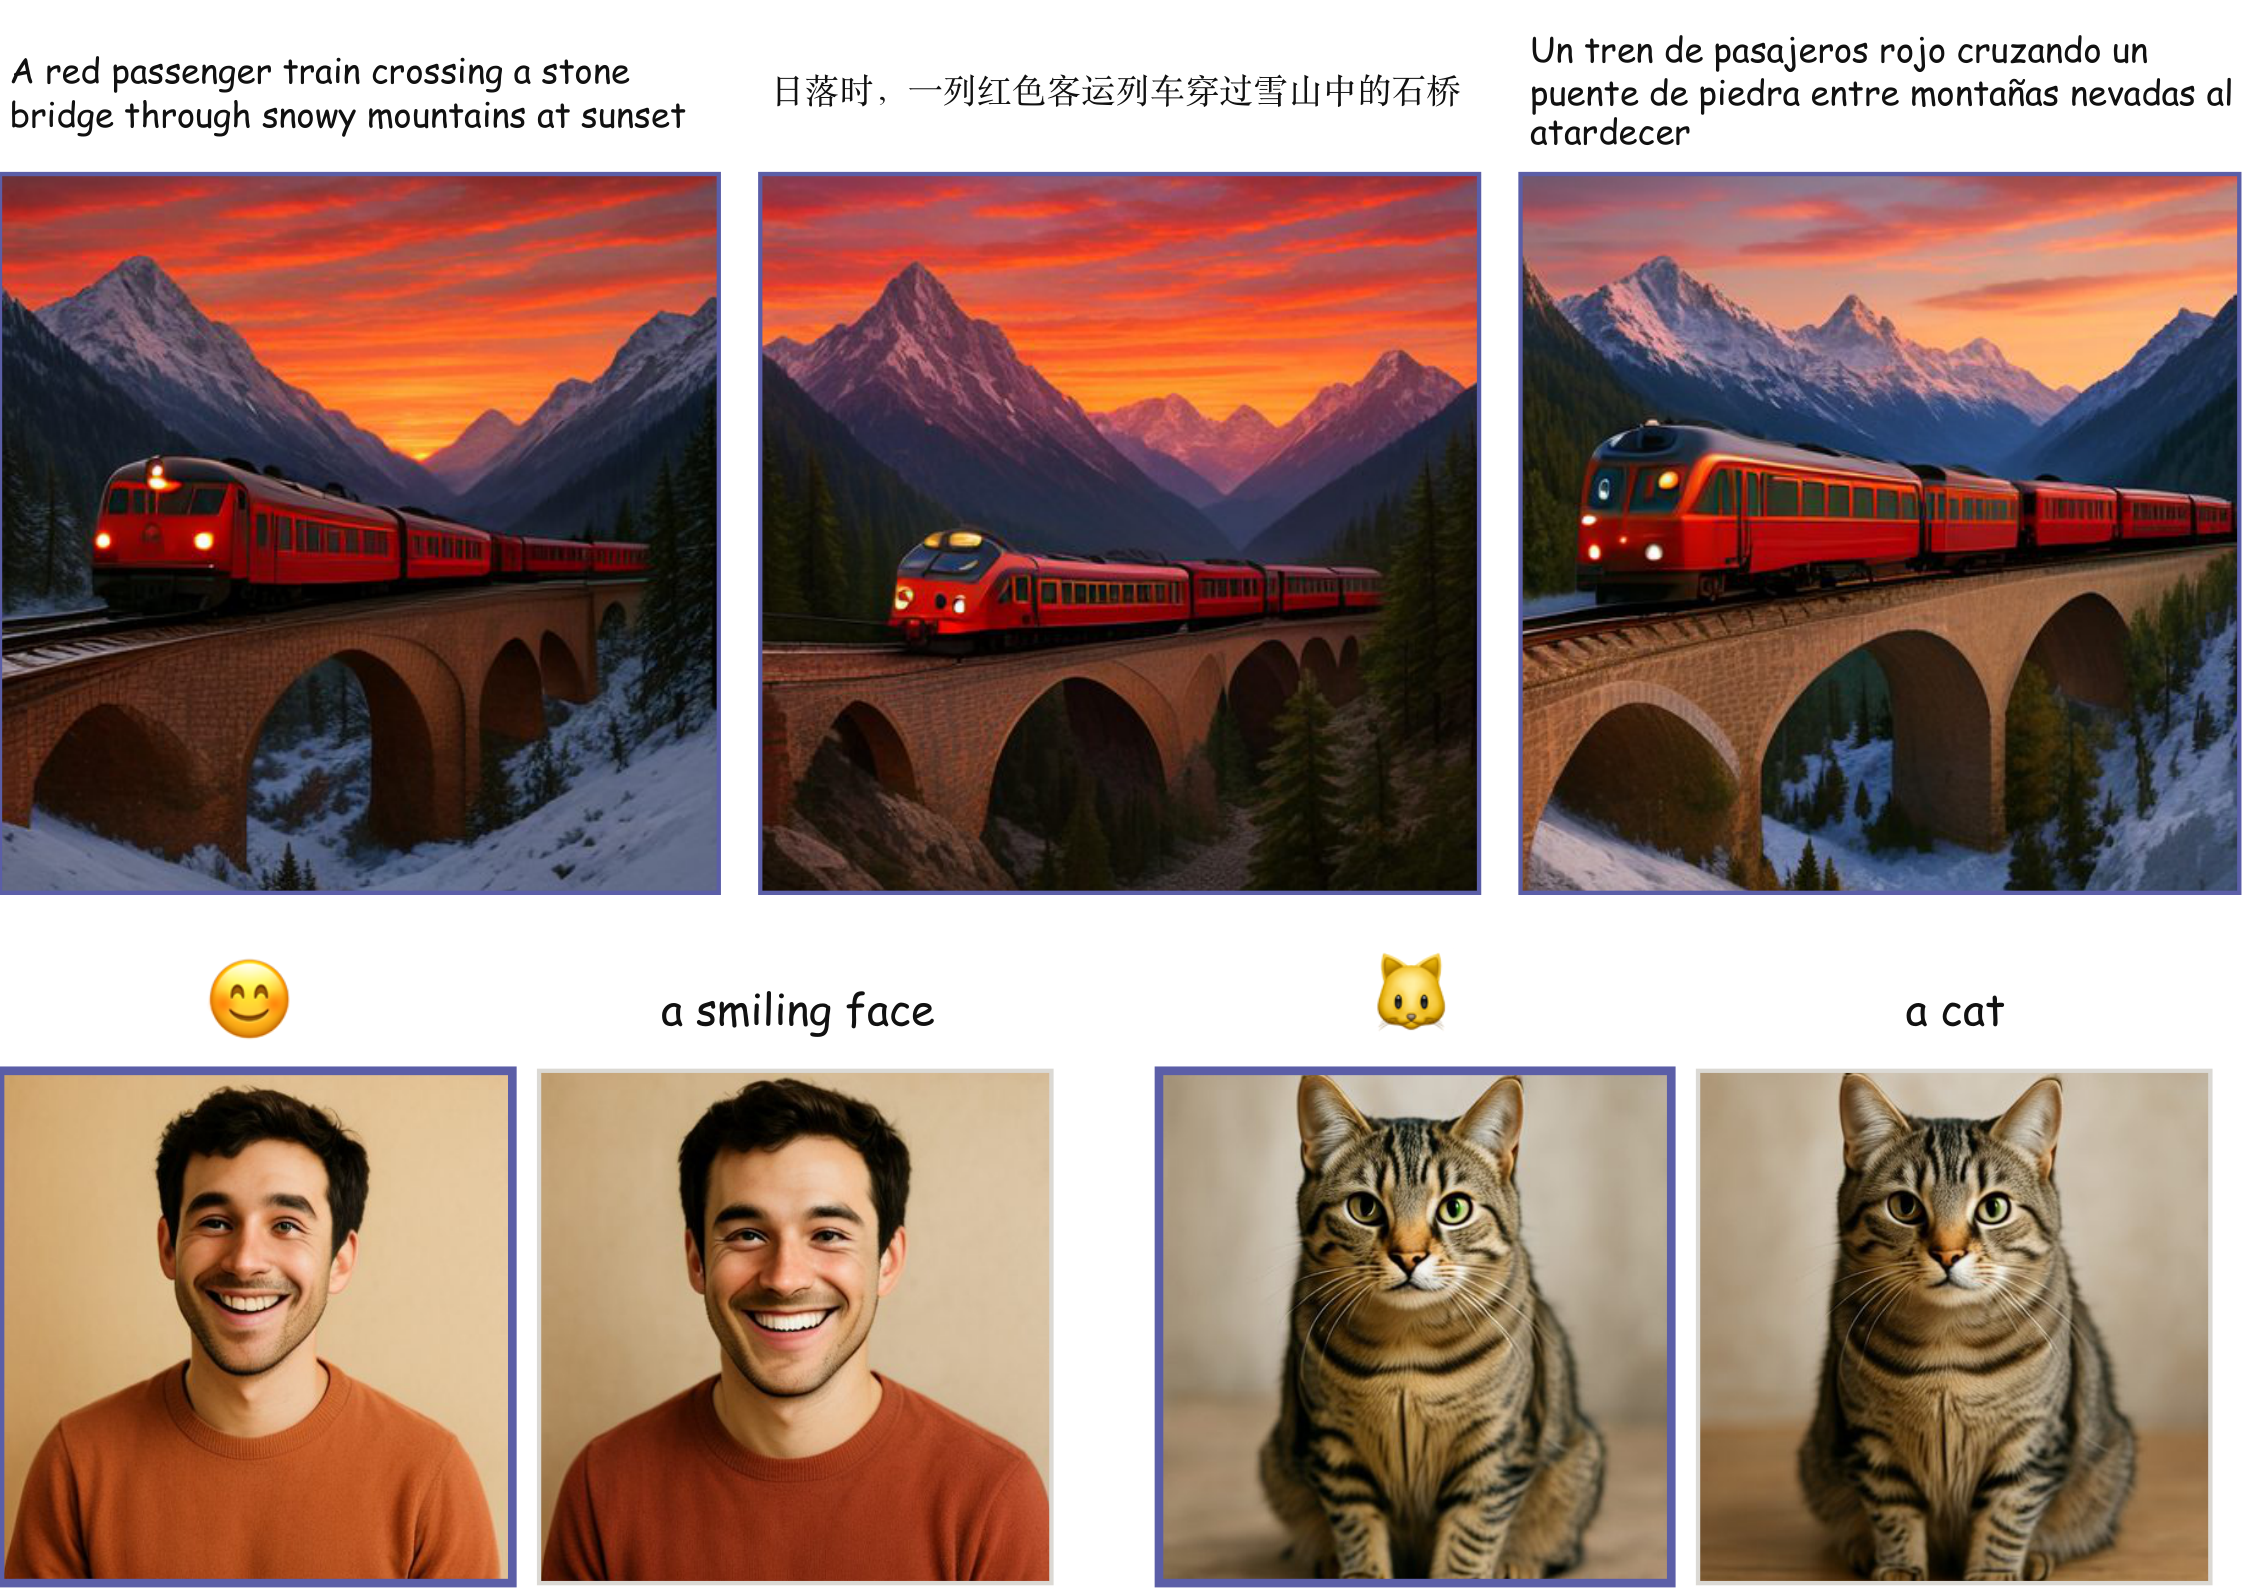
Multilingual and emoji prompts decoded by FLAT.
Semantically equivalent English, Chinese, and Spanish prompts produce consistent images. Emoji concepts can also be routed through the shared latent space.

Multi-frame video semantics

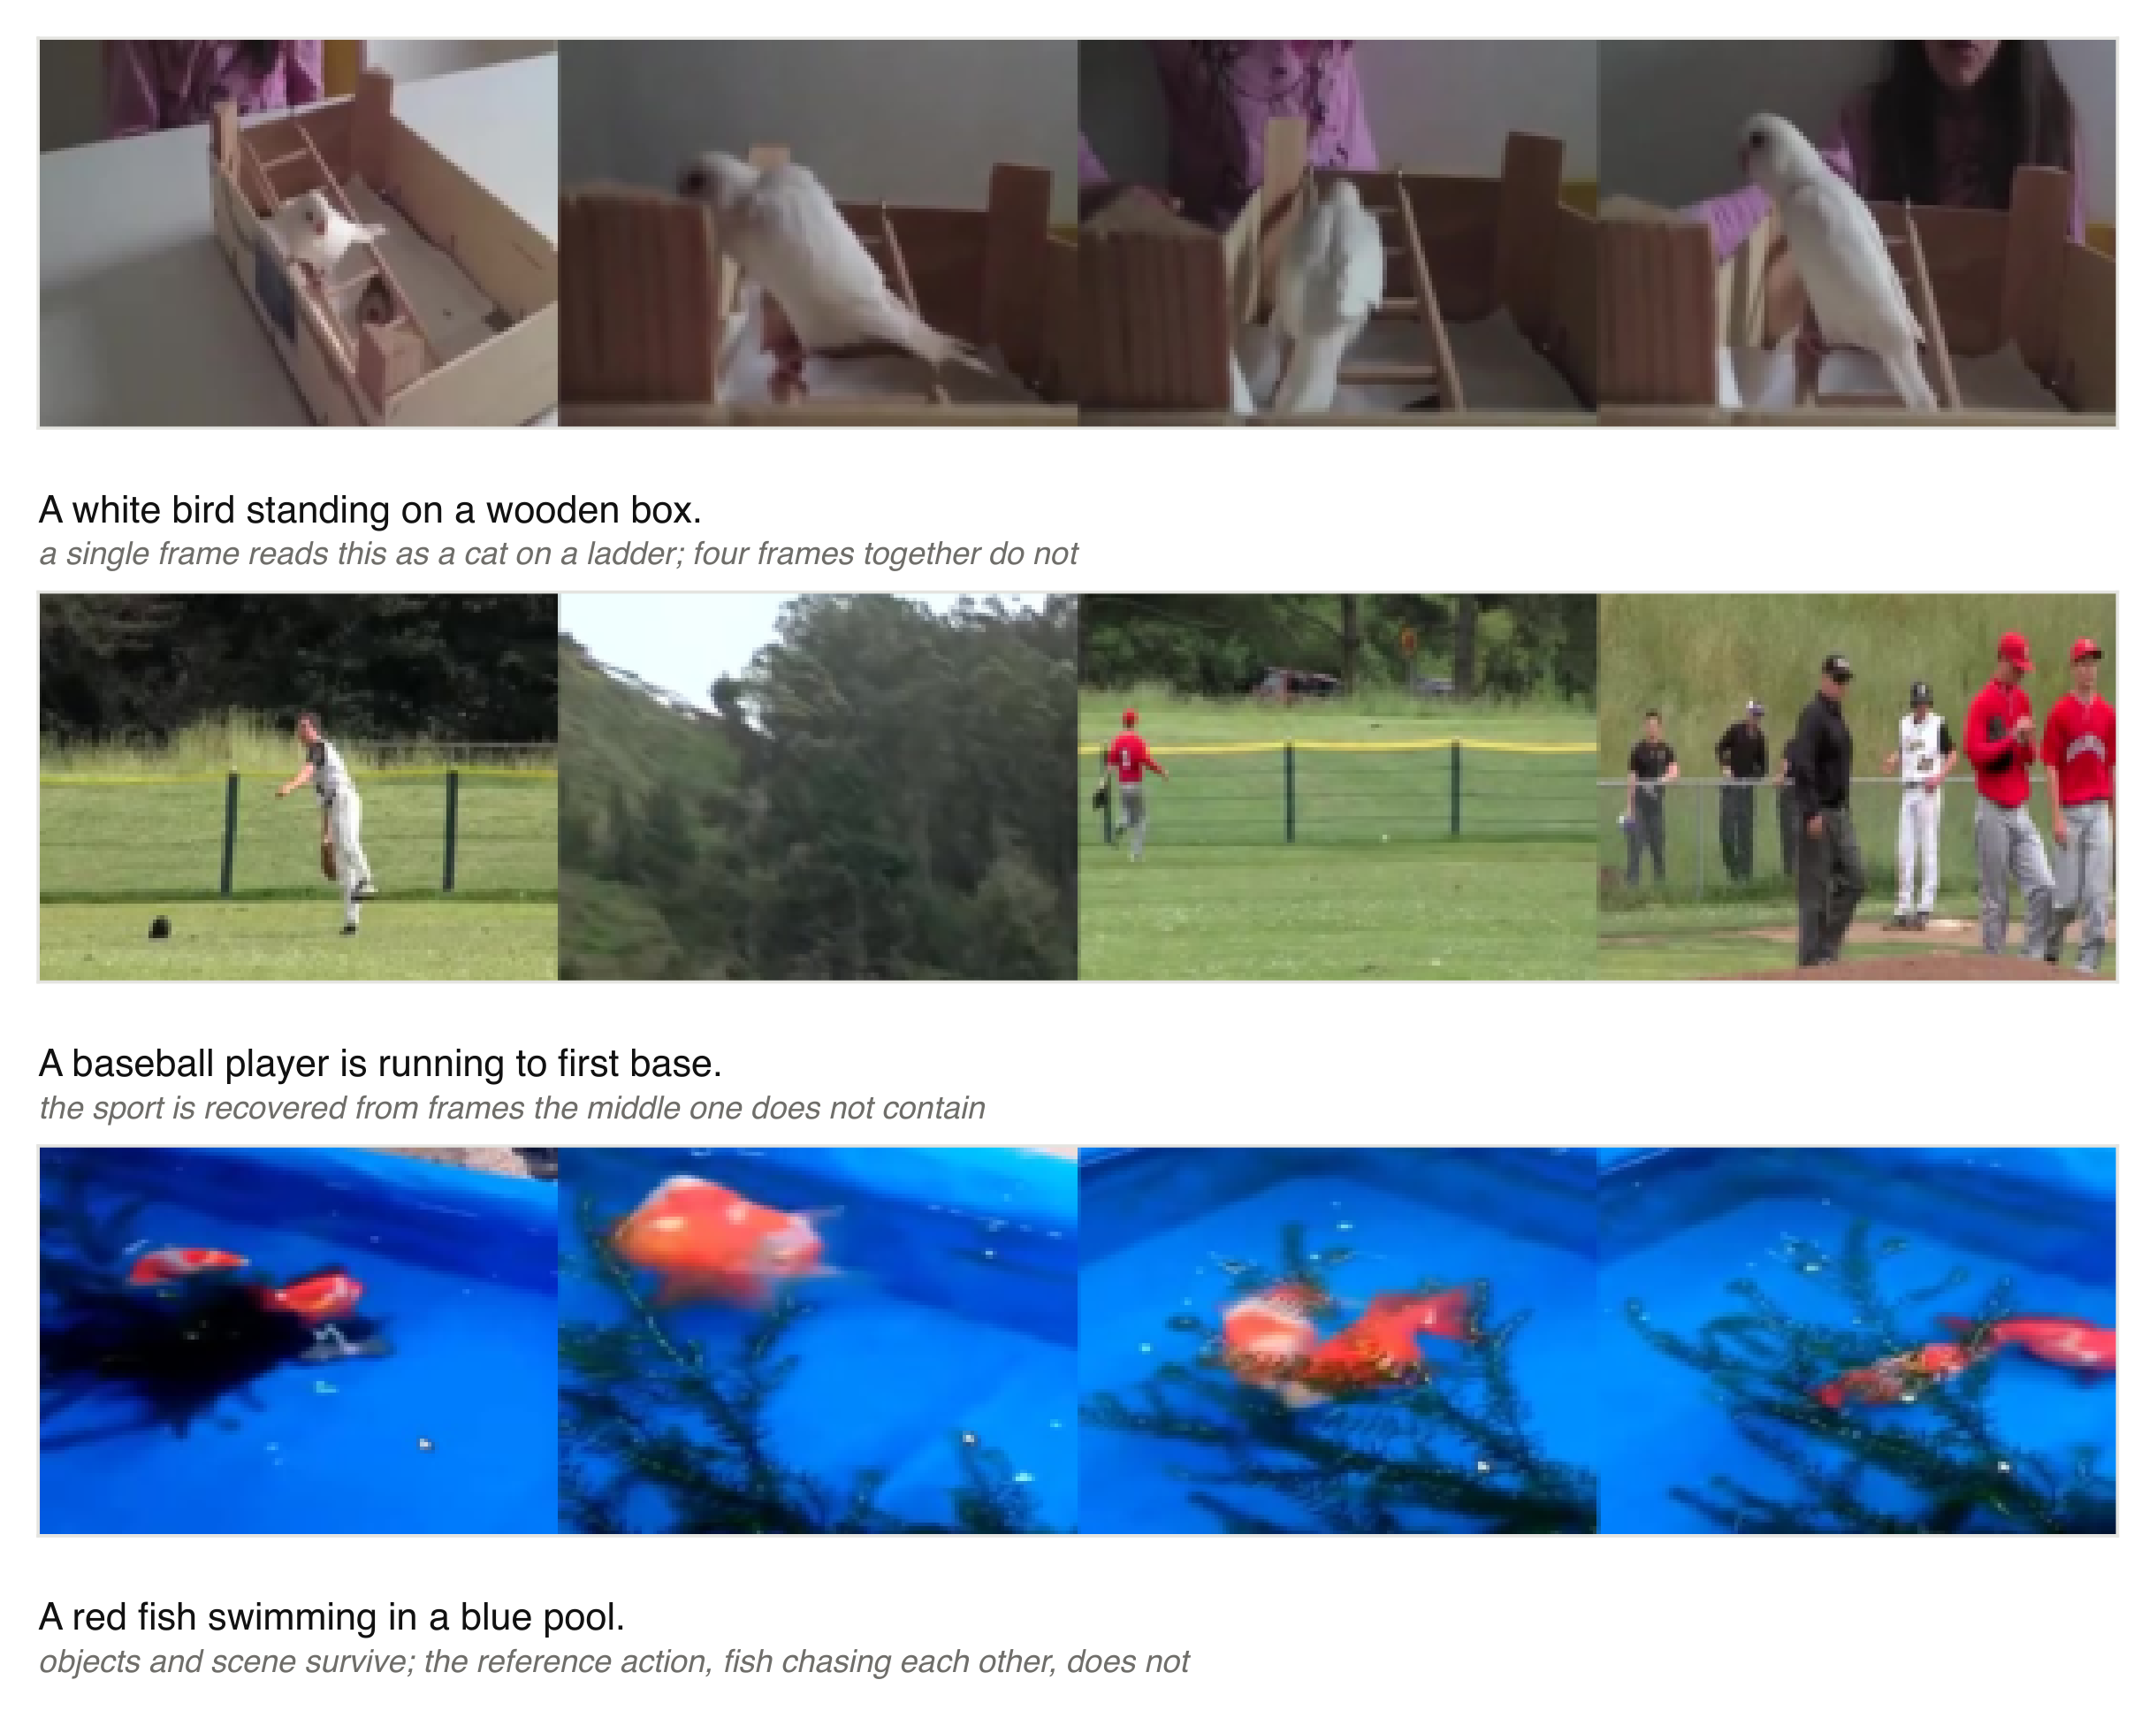
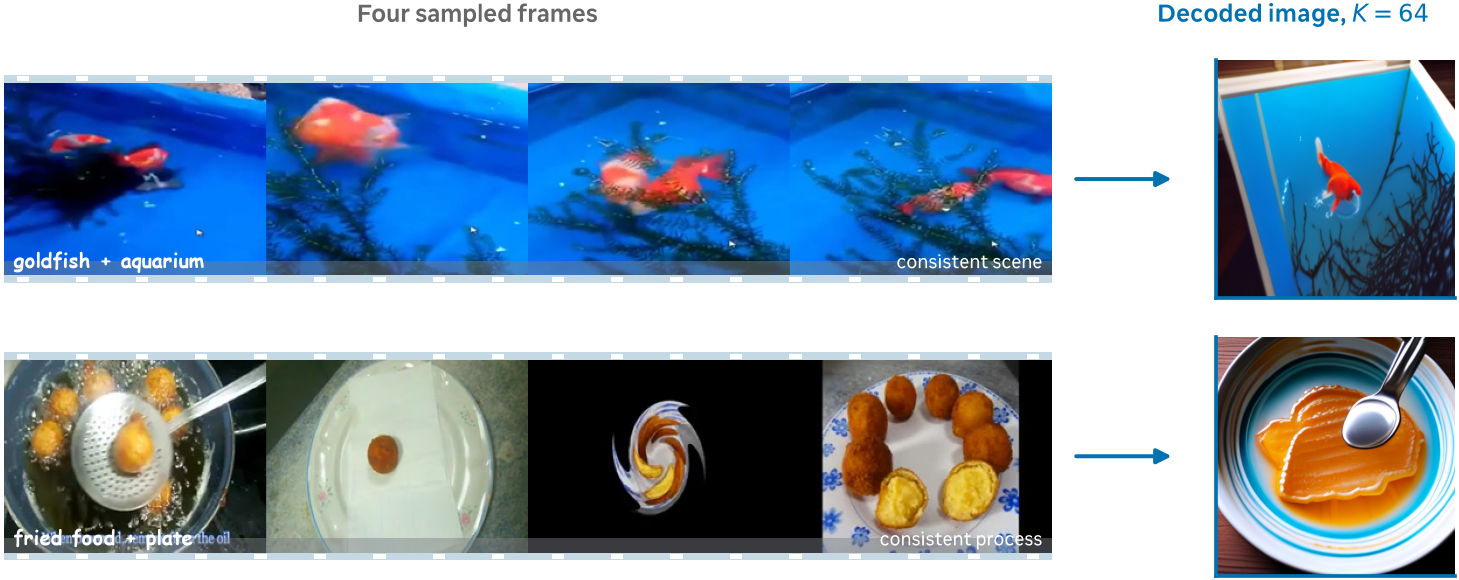
Four sampled frames can be jointly encoded into one register sequence. The decoded result fuses concepts distributed across the clip rather than selecting a single keyframe.

Zero-shot captions produced from multiple frames of a video clip.
Video-to-text. The caption decoder summarizes objects, scenes, and actions across sampled frames.
Images decoded from joint multi-frame video representations.
Video-to-image. The generated image combines persistent objects and scene context across multiple frames.

BibTeX

@misc{anonymous2026flat,
  title  = {FLAT: Resampling Image and Text into 1D Flexible-Length
            Aligned Transmodal Tokens for Retrieval and Generation},
  author = {Anonymous Authors},
  year   = {2026}
}